Local AI Explained: How Running AI Models on Your Own Hardware Works
How llama.cpp, Ollama, and quantization let you run AI models on your own hardware — real cost, hardware, and setup guidance, not just theory.
How llama.cpp, Ollama, and quantization let you run AI models on your own hardware — real cost, hardware, and setup guidance, not just theory.
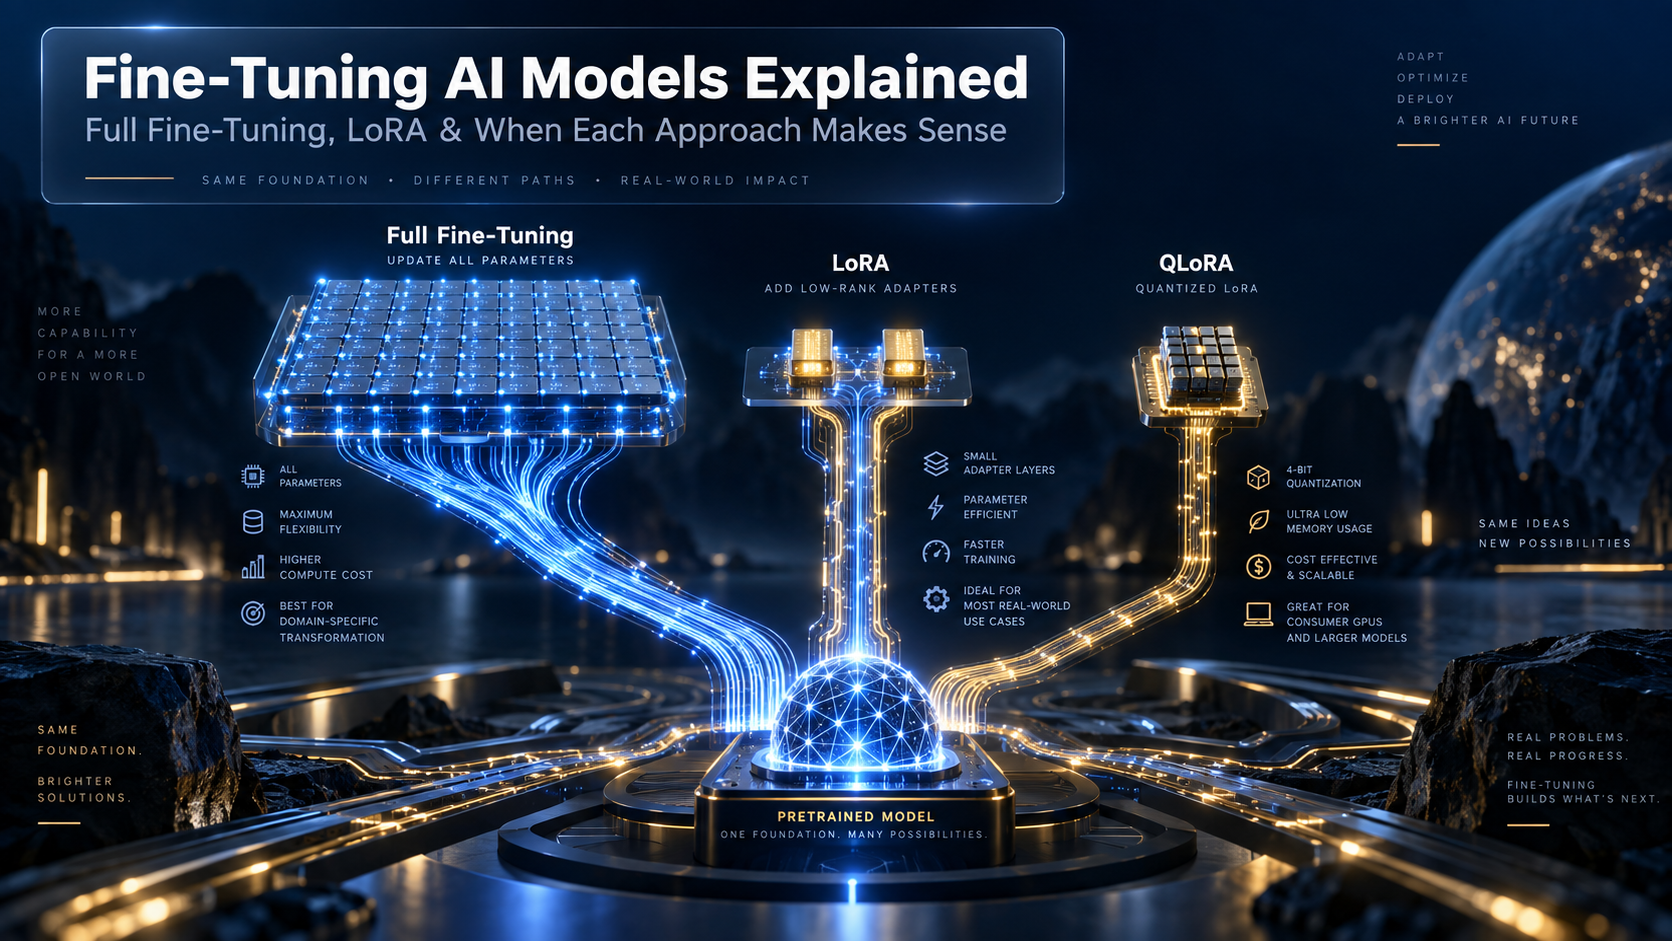
Fine-tuning adapts a pre-trained AI model to your specific task by updating its weights — but full fine-tuning, LoRA, and QLoRA solve this very differently. This guide breaks down how each method works, what it actually costs in VRAM and dollars, how much data you need by task type, and which approach to choose using the AHW Fine-Tuning Decision Matrix 2026.