Evidence: Documentation reviewed
Last checked: September 2026
What was done: Written from official documentation and the published sources linked in this article. Not hands-on tested.
Files: None
Affiliate links: No
How to Optimize Blog Posts for ChatGPT, Perplexity & Gemini
Your Blog Post Can Rank—and Still Be Invisible to AI Search
There is a frustrating moment that more publishers are starting to encounter: an article can be perfectly legitimate by traditional SEO standards, yet fail to appear when a person asks an AI search system the question that article was built to answer. The publisher may have researched the topic carefully, covered the obvious keywords, earned some organic visibility, and built a page that looks excellent in a conventional search result. Yet when the same subject is explored through ChatGPT, Perplexity, Gemini, or an AI-driven search experience, another publisher becomes the source that gets surfaced, summarized, or cited.
That does not automatically mean the competing page is “more optimized for AI.” In many cases, the real difference is deeper. AI-mediated search systems can treat a webpage not simply as a destination to rank, but as a source of information that may be discovered, retrieved, interpreted, compared with other sources, and selectively used to construct an answer. Google’s current documentation makes this distinction especially clear for AI Overviews and AI Mode: the foundational SEO requirements still matter, there are no additional technical requirements or special AI markup requirements, and pages must still be crawlable, indexable, useful, and eligible for normal Search. At the same time, Google explains that AI Mode can break a complex question into subtopics and search for those subtopics simultaneously, which changes the information environment in which a publisher’s page competes.
That leads to a much more useful question than “How do I make ChatGPT rank my article?” The better question is: How do I make the information on my article genuinely useful to a retrieval-and-answer system? That question shifts attention away from superficial platform tricks and toward the qualities that make content discoverable, understandable, evidence-backed, extractable, and worth citing in the first place.
This distinction matters because there is no reliable universal “ChatGPT formatting hack,” “Perplexity ranking formula,” or “Gemini heading trick” that publishers can follow as a guaranteed formula. OpenAI explicitly says ChatGPT Search ranks results using multiple factors and that placement is not guaranteed. Perplexity documents its crawler access rules and states that pages blocked from PerplexityBot will not have their full or partial text indexed. Gemini’s own documentation confirms that it may provide sources and related links, but not every response contains them. In other words, the interfaces are different, the retrieval paths can change, and the visible answer is only the final layer of a much larger system.
The durable strategy is therefore not to create three different versions of the same article for three different AI platforms. It is to build one strong information asset that can survive changes in how those systems discover and present information, while still respecting the technical and editorial conditions that each environment actually documents.
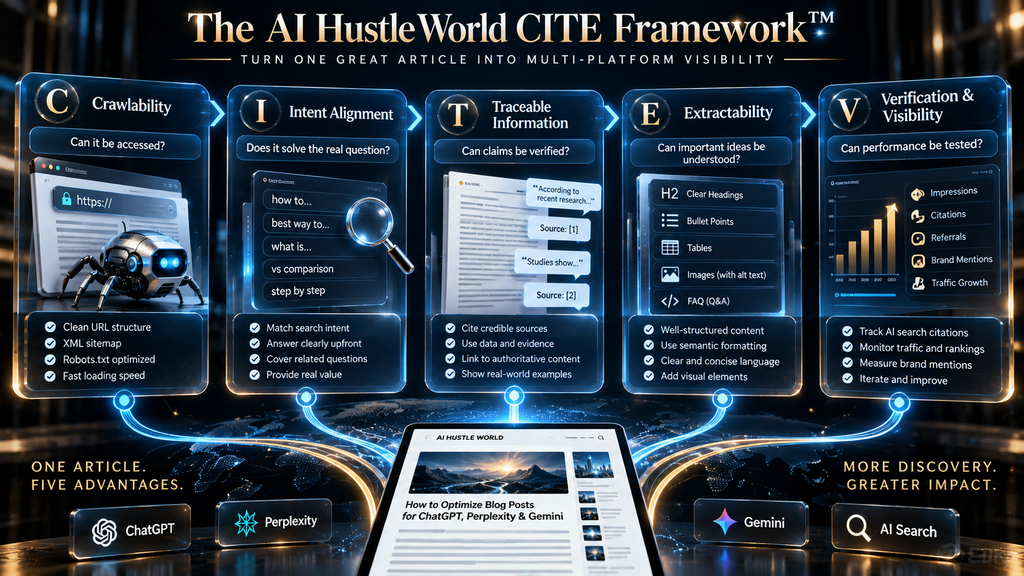
This guide develops that strategy through the AI Hustle World CITE Framework, a practical model built around Crawlability, Intent Alignment, Traceable Information, Extractability, and Verification & Visibility. The purpose of the framework is not to manufacture an artificial “AI-friendly” writing style. It is to help you turn an ordinary blog post into a more complete, defensible, and retrievable information resource.
Quick Answer: How Should You Optimize a Blog Post for ChatGPT, Perplexity and Gemini?
The strongest approach is to optimize the information quality and accessibility of the article rather than trying to reverse-engineer a secret ranking formula for each platform. Start with normal SEO foundations such as crawlability, indexability, internal linking, useful page structure, strong content, and accurate structured data; then improve the article so that it directly satisfies the underlying user question, makes important claims easy to verify, presents useful information in clear contextual units, demonstrates genuine originality, and remains current when facts change. Google explicitly says its normal SEO best practices remain relevant to AI features and that there are no additional AI-specific technical requirements, while OpenAI and Perplexity document crawler access as an important condition for discoverability.
The practical objective is not to “force” a citation. A citation is an outcome you cannot guarantee. What you can control is whether your page contains information worth retrieving and citing, whether the system can access that information, whether the relevant passages make sense outside the surrounding page, whether the claims are sufficiently traceable to evidence, and whether your article contributes something more useful than another generic summary of the same material.
That distinction is the foundation for everything that follows.
Why AI Search Changes the Content Journey
Traditional SEO encourages publishers to think in terms of pages competing for visibility. A user enters a query, a search engine returns a collection of links, and the publisher’s objective is to earn a prominent position that earns the click. Although modern search has always involved much more than simple keyword matching, the mental model remains relatively straightforward: query, results, click, page.
AI-mediated search introduces more possible stages between the question and the final interaction with a publisher. A conversational system may need to interpret a natural-language question, expand or reformulate it, identify relevant sources, retrieve useful passages, compare conflicting or complementary information, synthesize an answer, and then decide which sources to surface to support that answer. Google explicitly describes “query fan-out” in AI Mode, where a complex question can be divided into subtopics that are searched simultaneously. OpenAI says ChatGPT Search can use multiple targeted queries and ranks results using multiple factors. These documented behaviors do not prove that every AI system follows one identical pipeline, but they demonstrate why optimizing only for the exact phrase in the original user query is an increasingly narrow strategy.
Consider a user who asks, “What is the best AI meeting-notes tool for a five-person consulting business, and what should we look out for?” That is not one information need. It contains at least a definition of the product category, a recommendation problem, a company-size constraint, a workflow question, and a risk-assessment question. A strong article may be relevant to several parts of that decision even if it never contains the exact natural-language wording of the user’s question. A weak article may contain the target keyword dozens of times and still fail to supply the evidence, comparison criteria, or practical context required to answer the real question.
This is where many AI-search optimization guides go wrong. They take the visible interface and ask what formatting pattern might make a page easier for a machine to “like.” The more durable approach is to ask what information problem the page solves. Is the reader learning a concept, comparing alternatives, troubleshooting a problem, implementing a workflow, evaluating risk, or deciding whether a product or strategy is appropriate? The structure, evidence, examples, and level of detail should follow that purpose rather than a generic optimization checklist.
That principle also explains why answer-first writing is useful but insufficient. Giving the answer early makes a relevant passage easier for a reader and potentially easier for a retrieval system to identify. But if the article stops after a compressed answer, it becomes shallow. The real advantage comes from pairing a clear answer with the reasoning, conditions, evidence, examples, exceptions, and practical implications that make the answer trustworthy and reusable.
The First Principle: Optimize the Information, Not the Interface
The most durable strategy for AI search is to avoid optimizing around the current interface of an individual platform. ChatGPT can change the way it performs web search. Perplexity can change the way it displays or evaluates sources. Gemini can change how source links are exposed. Google can change how AI Overviews and AI Mode assemble and present retrieved information. Google itself says its AI search experiences can use different models and techniques, and the set of responses and links shown can vary.
That creates an important strategic distinction between platform optimization and information optimization.
Platform optimization asks, “What does this interface appear to prefer today?” Information optimization asks, “What makes this page a strong source regardless of how a system retrieves and presents it?” The second question leads to practices that tend to age better because they are based on information quality rather than UI behavior. A clear definition remains useful if the answer box changes. An original dataset remains valuable if citation cards are redesigned. A well-supported comparison remains useful if the retrieval model changes. A page that is technically inaccessible, by contrast, remains inaccessible regardless of how cleverly its headings are written.
This is why Google’s documentation is so important to the broader strategy. Google does not tell publishers to create a new class of “AI pages.” It says that the same foundational SEO practices remain relevant to AI features and explicitly states that no additional technical requirements, special AI text files, or special schema.org markup are necessary. What it does emphasize includes crawlability, internal links, good page experience, textual availability of important content, helpful media where applicable, and structured data that matches visible content.
The implication is not that every platform behaves identically. They do not. The implication is that the publisher’s base asset should be strong before any platform-specific consideration is added. That is the difference between building an information system and trying to game an interface.
The AI Hustle World CITE Framework
The CITE Framework exists because generic advice such as “write good content,” “use headings,” and “build authority” is directionally correct but operationally weak. A publisher needs a way to inspect a specific article and determine where its information architecture or evidence may be failing.
CITE begins with Crawlability, because no amount of editorial quality can compensate for a system being unable to access the page. It then moves to Intent Alignment, because the article has to solve the problem behind the query rather than merely repeat related terms. The third layer, Traceable Information, asks whether important claims can be verified through evidence, sources, examples, and explicit context. Extractability concerns whether the important ideas can be identified and understood without forcing the reader—or a retrieval system—to reconstruct the author’s meaning from scattered fragments. Finally, Verification & Visibility turns the framework from a writing exercise into an operating process: you test the content, monitor how it performs, and distinguish assumptions from evidence.
The framework is useful because the five layers are sequential in practice but interdependent in outcome. A perfectly crawlable article with weak evidence may be easy to retrieve and still not deserve trust. An original, heavily researched article that cannot be crawled by an important search crawler may never become a meaningful source in that environment. A beautifully written comparison that forces its recommendation criteria into ambiguous language may be difficult to extract accurately. And a technically sound article that is never measured can leave the publisher believing an optimization strategy worked when nothing meaningful changed.
CITE is therefore best understood as an editorial operating system, not a formatting checklist.
C — Crawlability: Can the System Actually Access the Article?
Crawlability is the least glamorous part of AI-search optimization, which is precisely why it is frequently neglected. Publishers are naturally drawn toward wording, headings, entities, semantic coverage, and content structure because those activities feel editorial. Yet if an important search system cannot access the page, the quality of the prose becomes largely irrelevant to that system.
For Google AI features, Google states that a page needs to be indexed and eligible to appear in Google Search with a snippet. It also reiterates conventional technical fundamentals, including allowing crawling, maintaining discoverable internal links, and ensuring important content exists in textual form. There is no additional “AI crawl” requirement layered on top of those normal fundamentals. (Google for Developers)
The same general principle appears explicitly in other systems. OpenAI says publishers who want their websites to be discoverable in ChatGPT Search should allow OAI-SearchBot to crawl the site, and the host or CDN needs to allow traffic from OpenAI’s published searchbot IP addresses. Perplexity likewise says PerplexityBot follows robots.txt and will not index full or partial text content from sites that disallow it. (OpenAI Help Center)
That makes the first practical audit surprisingly simple. Check whether important pages are crawlable. Check robots.txt. Check relevant noindex directives. Check whether critical content depends on an access path that crawlers cannot use. Check whether the page is discoverable through the site’s own internal links. Then consider the hosting layer: a restrictive CDN, firewall, bot-management system, or infrastructure rule can undermine discoverability even when the article itself is perfectly configured.
There is an important nuance here. “Crawlable” does not mean “guaranteed to be used.” OpenAI explicitly says search placement is not guaranteed. Google likewise says meeting requirements and best practices does not guarantee crawling, indexing, or serving. Perplexity says a blocked page may still have its domain, headline, and a brief factual summary indexed even though its full or partial text is not. The correct mental model is therefore access is a prerequisite, not a ranking promise.
I — Intent Alignment: Write for the Question Behind the Query
Keyword targeting still has value because language provides signals about what a page is about. The mistake is treating the keyword as the final objective. AI-mediated search makes this particularly limiting because users increasingly express complex goals rather than short keyword phrases, and systems can expand queries into related subtopics.
A strong optimization process therefore starts with the question: What is the user actually trying to accomplish?
Imagine a page targeting “AI customer support tools.” That phrase could correspond to several different intents. One reader may be trying to understand the category. Another may want to compare vendors. A third may want to calculate whether replacing one support agent is financially sensible. A fourth may already use an AI support system and be troubleshooting poor resolution rates. A page that attempts to satisfy all of those intents equally often becomes vague. It lists definitions, tools, features, prices, implementation advice, metrics, and predictions without giving enough depth to any one decision.
Intent alignment means choosing the primary job of the page and then making adjacent information support that job. A comparison article should not merely list features; it should establish evaluation criteria, explain trade-offs, identify who each option suits, and clarify where the comparison breaks down. A how-to article should not stop at a numbered sequence; it should explain prerequisites, dependencies, failure modes, and measurement. An educational guide should explain mechanisms instead of merely accumulating definitions.
This is one of the clearest places to improve AI-search performance without writing unnaturally for machines. When the article is tightly aligned with the user’s real objective, the content becomes richer in decision-relevant concepts. The page contains the kinds of information a system needs when it encounters a nuanced question: not just “what is X?” but “when is X useful?”, “what are the alternatives?”, “what can go wrong?”, “what evidence supports this?”, and “how would the decision change under different conditions?”
The result is broader relevance without keyword stuffing.
T — Traceable Information: Make Important Claims Defensible
The weakest content on the web often fails not because its sentences are grammatically poor, but because its claims cannot be confidently traced back to anything. An article may say that a tool is “better,” a strategy is “faster,” an approach “increases conversions,” or a technology “saves 40% of support costs” without clarifying where those conclusions came from.
AI search makes this weakness more consequential because answer systems have to reconcile information from multiple sources. Unsupported statements create ambiguity. A system may ignore the claim, attribute it incorrectly, combine it with another source, or simply reproduce the unsupported statement with unjustified confidence.
Traceability does not require every sentence to become academic writing. It means that important claims have an identifiable basis. That basis can be an official documentation page, a primary research paper, a transparent calculation, a disclosed experiment, a credible dataset, a case study, or a clearly labeled analysis. The source type should match the claim. A vendor’s pricing page is appropriate for the vendor’s current pricing. It is not automatically appropriate for proving that the vendor delivers superior business outcomes.
This is also where editorial honesty matters. The AI Hustle World production standard distinguishes among documented facts, research findings, company or vendor claims, AI Hustle World analysis, and illustrative examples. That distinction should remain visible in the writing even when formal labels are not placed around every paragraph. A sentence such as “OpenAI says…” is different from “AI Hustle World analysis suggests…” and both are different from “For example, a small agency might…” because the reader should be able to understand the epistemic status of the information.
Consider an article that says, “This workflow saves businesses 50% of support costs.” That is an outcome claim. To make it trustworthy, the publisher would need to define the population, baseline, measurement method, time period, and source. Without those details, the number looks precise while carrying very little evidentiary weight. A better article might instead explain the cost mechanism—ticket volume, automation coverage, resolution rate, escalation rate, human review, platform cost—and then show an illustrative calculation where the assumptions are explicitly stated. That approach is not only more credible for humans; it also produces cleaner information units that a retrieval system can interpret correctly.
Perplexity’s current source-label guidance reinforces the importance of publication-level trust signals. Perplexity says some domains receive Government, Academic, or Trusted labels based on a whole-site review that considers factors such as whether the publisher corrects mistakes, identifies authors, and separates editorial material from advertising and opinion. Perplexity also notes that a label is not a guarantee of the truth of an individual claim. (Perplexity AI)
That distinction is worth preserving. Trust is not a decorative badge. It is a property of the information system around the claim.
E — Extractability: Make the Important Ideas Easy to Identify Without Making the Writing Robotic
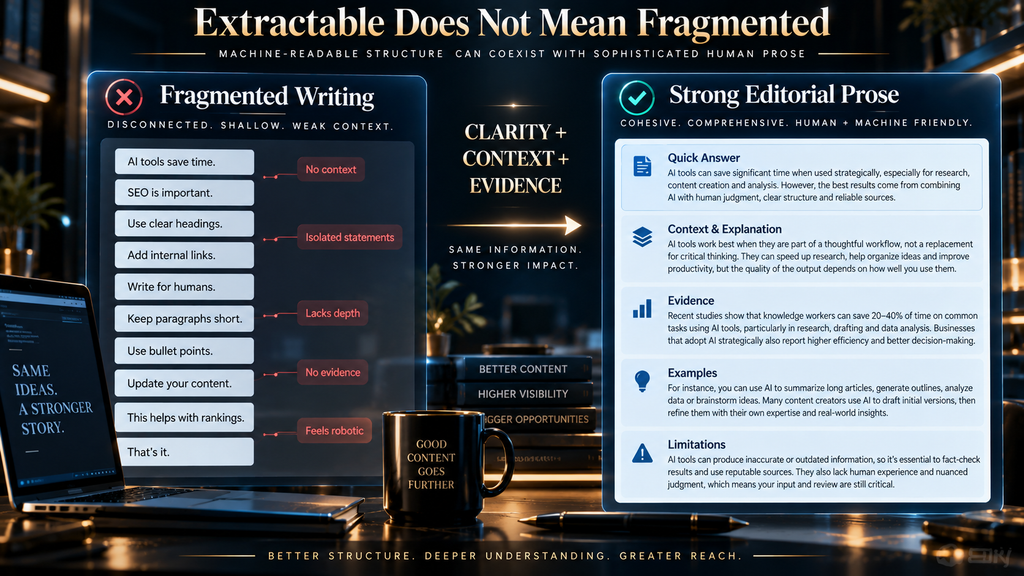
Extractability is perhaps the most misunderstood part of AI-search writing because publishers often interpret it as “make everything shorter.” That is not the objective.
Extractability means that important information has a clear semantic shape. A definition should define something unambiguously. A comparison should identify comparable dimensions. A procedure should contain a coherent sequence. A recommendation should explain the conditions under which it is appropriate. A limitation should be attached to the claim it qualifies instead of being buried several sections later.
This is one reason strong editorial prose and machine-readable structure do not have to conflict. Consider a paragraph explaining why an AI support platform can become expensive. If the article spends 500 words describing the company, discussing automation trends, and introducing the concept before eventually saying that cost depends on usage volume, resolution rate, human escalation, and implementation overhead, the core idea becomes difficult to locate. The problem is not that the paragraph is long. The problem is that the information hierarchy is weak.
A more extractable article makes the central statement clear and then develops it. It might explain that the economic value of AI support depends less on the number of automated messages than on the number of customer problems resolved without costly human intervention. The subsequent prose can then explain the mechanism, define the relevant metrics, describe exceptions, and show a calculation. The writing remains sophisticated, but the core idea is not hidden.
Tables can help when they compress genuinely comparable information. They become harmful when they simply decorate the article with repeated adjectives such as “best,” “powerful,” or “easy to use.” The same principle applies to headings. A heading such as “Things to Consider” provides very little semantic precision. A heading such as “How Retrieval Quality Changes When Evidence Is Missing” signals an actual conceptual shift and creates a useful boundary for the information that follows.
The critical point is that extractability should be achieved through clarity of thought, not by stripping away nuance.
That is a significant difference between good AI-search optimization and bad AI-search optimization. A page written entirely in short declarations may look highly extractable, but it can lose causal relationships, exceptions, context, and evidence. A better article allows the important statement to stand out while preserving the explanatory prose around it.
V — Verification & Visibility: Optimization Ends With Measurement, Not Publication
The final layer of CITE is the one publishers often skip because it is less satisfying than writing. You publish the article, see that the page is indexed, and assume the optimization worked. But indexation is not the same as meaningful visibility.
Verification means checking whether the page behaves the way the strategy predicts. Are users finding it through relevant questions? Is it receiving organic impressions? Are important queries producing visibility? Is the content attracting clicks or assisted conversions? Is the article being referenced in AI-mediated search environments when those citations or referrals are observable? Are third-party systems representing its claims accurately, or are they repeatedly misunderstanding an important part of the page?
Google says AI Overviews and AI Mode traffic is included in the overall web reporting in Search Console’s Performance report. Google also recommends using Search Console alongside analytics tools to understand how search exposure translates into traffic and engagement.
ChatGPT provides another useful measurement opportunity. OpenAI says referral traffic from ChatGPT Search can carry a utm_source=chatgpt.com parameter, allowing publishers to identify that traffic in analytics.
The deeper lesson is that AI-search optimization should be treated as an experimental content discipline. You should have a hypothesis before making major changes. For example, “The article currently answers the primary topic but lacks concrete comparison criteria and independent evidence, so improving those areas should increase usefulness for complex decision queries.” Then make the improvements and monitor meaningful signals over time.
This is better than changing headings randomly because an AI SEO tool produced a score of 87 instead of 72.
How to Rewrite an Existing Blog Post for AI Search
Most publishers do not start with a blank page. They already have hundreds of articles that were written for conventional search. The fastest route to better AI-search readiness is therefore often content rehabilitation, not endless new publishing.
Begin by identifying the article’s actual job. Ignore the current title for a moment and ask what problem the page is supposed to solve. Then inspect the article as if you were a reader who knows almost nothing about the subject. Where does the real answer appear? Which claims are unsupported? Which important concepts are assumed rather than explained? Where does the article repeat industry language without adding interpretation? Where does it present a recommendation without explaining the criteria behind it?
The next step is to inspect the article’s evidence architecture. Mark claims that depend on current facts, statistics, pricing, product features, regulations, or platform behavior. Some of those facts may have changed since publication. Others may have been weakly sourced from the beginning. Replace generic secondary claims with stronger primary or authoritative evidence where practical, and clearly distinguish vendor statements from independent findings.
Then examine the structure from a retrieval perspective. Could a reader identify the answer to the primary question from the relevant section without reading the entire article? Could a system accurately understand what the page means if it retrieved a few paragraphs from the middle? Does every important section have enough local context to make sense when separated from the introduction?
That final question is particularly important. Suppose a section says, “This is usually the better option for larger companies.” Better than what? Larger according to what definition? Why is it better? Under which conditions? A retrieval system may have access to the sentence while missing the contextual logic required to interpret it. The solution is not to avoid pronouns or write like a database. The solution is to make important claims locally intelligible.
A strong revision also removes commodity filler. If five competing articles all define “AI SEO” in almost identical language, another paragraph repeating that definition contributes almost no information gain. The space is better used explaining how the concept applies to the article’s specific decision, where the traditional approach fails, or what most competitors misunderstand.
The Difference Between “Answer-First” and “Shallow”
Answer-first formatting is valuable because people do not want to read two thousand words before discovering the article’s actual position. But a common mistake is to interpret answer-first as “one sentence per idea.”
That creates the exact type of fragmented content that feels machine-generated.
An expert publication can answer early and still develop the subject deeply. Imagine an article explaining whether a business should use AI for customer support. The opening might give a concise answer: AI support works best when the business has high-volume, reasonably structured requests and a clear escalation path; it is much less attractive when the majority of support interactions require judgment, negotiation, or sensitive exceptions. That sentence is useful because it gives the reader the governing principle immediately.
The rest of the section should then earn the conclusion. It can explain why volume and structure matter, how resolution rate affects economics, why escalation changes total cost, which support categories are suitable, what implementation mistakes damage customer experience, and what a small business should measure before expanding automation.
That is what answer-first writing is designed to produce: the answer first, then the reasoning and nuance required to trust it.
The article should feel dense with reasoning rather than dense with formatting. That is a crucial distinction.
Original Information Is the Strongest Long-Term Advantage
There is a ceiling to how much authority you can build by summarizing what everyone else has already said. An article can be accurate, polished, and comprehensive while still contributing almost nothing new.
Google’s own guidance for succeeding in AI search repeatedly emphasizes unique, satisfying, original content and information that adds value rather than repeating commodity material.
Originality does not require a laboratory. It can come from a real test, a documented workflow, an original comparison, a transparent calculation, a proprietary framework, a dataset created by the publisher, a firsthand observation, an original analysis of existing data, a genuine case study, or a clearly documented failure mode that competitors rarely explain.
The important word is genuine.
A fake case study does not become original simply because nobody else has published it. A fabricated test is not experience. An invented statistic is not proprietary research. And a “framework” that merely renames five generic SEO recommendations is not a meaningful intellectual contribution.
Suppose you are writing about AI keyword research. Instead of saying that AI tools save time, you could document a repeatable workflow showing how a seed topic becomes a query set, how those queries are clustered, how intent conflicts are identified, how overlapping articles are removed, and how the final content architecture is decided. That workflow becomes original even if every individual component is familiar because the synthesis, decision logic, and evidence are yours.
The same principle applies to comparative content. Ten existing articles may all compare pricing and features. Your article becomes more valuable when it explains which features matter under different business conditions, calculates total cost of ownership, surfaces implementation risk, or demonstrates that the tool with the most features is not necessarily the best fit for the intended workflow.
This is how information gain compounds.
Entity Clarity: Make It Obvious What the Page Is Actually About
AI systems work with concepts and relationships, not only keyword strings. That means entity clarity becomes increasingly important as questions become more conversational and multidimensional.
Entity clarity sounds technical, but the editorial practice is straightforward. Define important products, companies, technologies, methods, people, categories, and concepts precisely enough that the reader understands how they relate to the rest of the article.
For example, an article about “AI search” should distinguish among traditional search engines, AI features inside conventional search engines, standalone answer engines, and general-purpose AI assistants that can browse the web. These concepts overlap, but they are not interchangeable. A page that treats them as one thing may produce elegant prose while giving the reader a misleading mental model.
The same principle applies within a sentence. If an article says “it ranks better,” the reader should know what “it” is and what kind of ranking is being discussed. If a comparison refers to “the platform,” the article should make clear which platform is under discussion. Ambiguity is not merely a style flaw; it increases the chance that a retrieved passage will be misunderstood when separated from the rest of the article.
This is especially important for articles that compare several products or concepts. Keep category boundaries stable. Do not switch casually between “AI search,” “AI answer engines,” and “AI assistants” as though they are synonyms. A strong article teaches the reader the conceptual map while using terminology naturally.
Evidence Should Be Attached to the Claim It Supports
One of the simplest improvements you can make to an article is to move evidence closer to the claim it actually supports. Consider two versions.
The first says that an AI tool “cuts support costs dramatically,” then spends five sections discussing implementation, before eventually linking to a study near the end. The second explains that the claim comes from a vendor-reported result, identifies the conditions or limitations where known, and then distinguishes that statement from independent evidence.
The second version is superior because the reader does not have to remember or reconstruct the evidence chain. The claim and its qualification travel together.
This also reduces a common failure mode in AI-generated content: citation drift. Citation drift occurs when an article places a source near a group of claims, creating the visual impression that all of them are supported even though the source only supports one. Human readers make this mistake too, and retrieval systems can inherit it.
A more rigorous approach asks, “What exactly does this source prove?” Then write only what the evidence justifies.
That does not mean every paragraph needs a citation. Editorial reasoning, transitions, explanations, and obvious logical inferences do not need to become citation clutter. It means that factual, consequential, or time-sensitive claims should have a defensible basis appropriate to their importance.
Structured Data Helps Understanding, but It Is Not an AI Citation Hack
Structured data is often dragged into AI-search discussions as though adding more schema automatically makes a page more visible in AI answers. That is not supported by Google’s current guidance.
Google explicitly says there is no special schema.org structured data required for AI Overviews or AI Mode. It does recommend that existing structured data accurately match the visible text on the page.
That distinction matters because structured data is useful for clarity and eligibility, not magic.
If your article has an author, date, organization, product, recipe, event, or other appropriate entity, structured data can help systems understand what the page represents. But creating fabricated entities or adding markup that does not correspond to visible content introduces a trust problem rather than solving one.
The same logic applies to FAQ markup. An article can have genuinely useful questions and answers without needing to turn the page into a schema project. The information quality matters more than the markup theater.
A useful rule is simple: markup the information you already publish accurately; do not publish information merely because you think a machine-readable field might help it rank.
Freshness Is About Meaningful Change, Not Date Manipulation
AI search intensifies the importance of freshness because outdated information can be actively harmful when a system is asked a current question. Pricing changes. Products change. platform behavior changes. Policies change. Search interfaces change. A page that was correct eighteen months ago can become misleading even when its central concept remains valid.
But freshness does not mean changing the publication date every few months.
A fake freshness signal is easy to create and does not improve the underlying information. A meaningful update changes something substantive: pricing, examples, screenshots, data, conclusions, tool capabilities, source references, implementation instructions, or the interpretation of the subject.
This is consistent with a broader editorial principle: keep the stable intellectual core stable, and update the parts of the article that reality has changed.
For an evergreen guide to AI search optimization, for instance, the principle that crawlability matters may remain stable while the exact crawler documentation, product behavior, interface, or reporting capability changes. The publisher should preserve the durable explanation while updating the current facts.
This approach also makes maintenance more efficient. Instead of rewriting a 7,000-word article from scratch every time a platform changes one feature, maintain a distinction between conceptual content and volatile evidence.
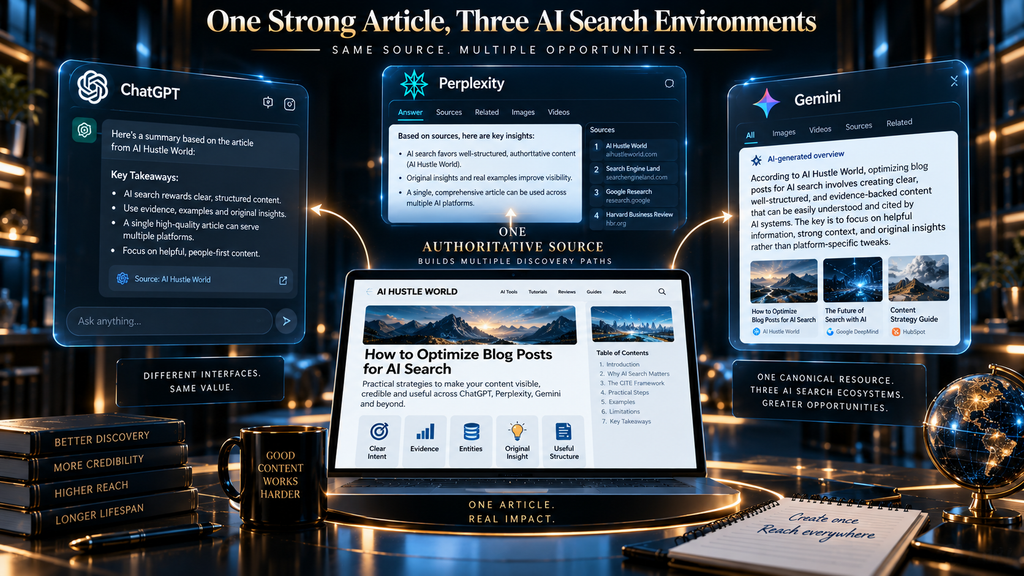
One Article for Three Platforms, Not Three Frankenstein Articles
The temptation is obvious. If you are optimizing for ChatGPT, write a ChatGPT section. If you are optimizing for Perplexity, create a different structure. If you are optimizing for Gemini, add special Gemini formatting.
There is some value in platform-specific knowledge, but the wrong implementation creates a mess: duplicated pages, awkward prose, inconsistent facts, and a site architecture built around temporary interfaces. A better model is a canonical information asset with platform-aware accessibility.
The central article should be written to solve the user’s problem. Then the publisher should make sure that the technical access conditions of each important environment are respected and that the article contains clear, evidence-backed information that can survive different retrieval methods.
That strategy is strengthened by the current documentation from all three ecosystems. OpenAI tells publishers to allow OAI-SearchBot when they want content to be discoverable in ChatGPT Search. Perplexity explicitly documents its crawler and robots.txt behavior. Gemini documentation explains that sources and related links may appear, but that source presentation is not guaranteed in every response. None of those documents says that publishers should create a bizarre “AI-native” writing format that abandons normal editorial principles.
The result is a more resilient publishing model. You build one strong article that earns the right to be retrieved, rather than three fragile versions designed around screenshots of today’s interface.
Optimizing Specifically for ChatGPT
ChatGPT deserves special attention because conversational search can change the relationship between a query and the underlying webpage.
OpenAI says ChatGPT Search ranks results using multiple factors, and placement is not guaranteed. It also says that websites should allow OAI-SearchBot to crawl them if publishers want their content to be discoverable, surfaced, and clearly cited and linked in ChatGPT Search.
The practical editorial implication is that query-family coverage matters more than exact phrase repetition. A user may ask a long conversational question whose underlying information need spans multiple related concepts. A strong article should therefore answer the primary question and cover the adjacent concepts that naturally determine the answer.
Suppose the article targets “best AI keyword research tools.” A shallow page might list ten products. A stronger page would explain what counts as useful AI keyword research, which workflow each tool supports, where AI-generated keyword ideas fail, how to validate generated suggestions against actual search behavior, and which tool characteristics matter for different publishing situations. That article contains more useful information for a conversational system because it provides not just entities and features, but decision logic.
Another important discipline is not overstating OpenAI-specific ranking claims. The fact that OAI-SearchBot access matters for discoverability does not mean that allowing the crawler guarantees citation. It does not. The system uses multiple factors, and placement is not guaranteed.
That distinction should be preserved every time.
Optimizing Specifically for Perplexity
Perplexity’s documentation provides one of the clearest examples of why technical accessibility and source quality belong in the same conversation.
Perplexity says its crawler, PerplexityBot, follows robots.txt and will not index the full or partial text of a site that disallows it. The company also states that blocked pages may still have their domain, headline, and a brief factual summary indexed.
For publishers, the strategic takeaway is that access rules can change the amount of information a system has available to work with. A title and summary are not equivalent to the full article. A page may therefore be technically visible in a limited way while the deeper evidence and explanations that make it valuable remain inaccessible.
Perplexity’s source-label system provides another useful lesson. Some domains are marked Government, Academic, or Trusted based on a whole-site review that considers factors including corrections, authorship, and separation of editorial material from advertising and opinion. Perplexity explicitly warns that labels do not guarantee the accuracy of a particular claim, but the system demonstrates that source context is part of how information quality is communicated to users.
This reinforces an important editorial principle: your article is not an isolated object. It lives inside a domain with authors, publishing practices, corrections, editorial standards, and accumulated reputation. A single polished page cannot compensate for a site that looks anonymous, unmaintained, or commercially deceptive.
That is why publisher-level trust practices—clear authorship, corrections, transparent methodology, accurate claims, and separation between editorial analysis and advertising—are not just brand polish. They contribute to the information environment surrounding every article.
Optimizing Specifically for Gemini and Google AI Search
Gemini requires a slightly different treatment because “Gemini” can refer to different experiences inside Google’s broader ecosystem. The safest editorial strategy is not to claim a secret Gemini ranking system, but to anchor optimization around documented Google Search principles and then recognize that Gemini-powered experiences may expose information differently.
Google’s current AI Search guidance says the normal SEO foundations remain relevant and that there are no additional technical requirements for appearing in AI Overviews or AI Mode. Google emphasizes crawlability, indexability, internal links, textual content, page experience, relevant media, and accurate structured data.
Google’s AI Mode documentation also explains that complex questions can be divided into subtopics and searched simultaneously. That makes comprehensive topical coverage more strategically important than simply matching a single phrase. An article should make the important relationships among concepts explicit so that a page can contribute useful information to multiple aspects of a more complex question.
Gemini’s user-facing documentation confirms that source and related-content links may appear, including links to public websites, uploaded files, and connected Workspace information where applicable, but not every response includes sources.
The implication for publishers is subtle but important. Do not interpret the occasional absence of a source link as proof that an article was not used, and do not interpret the presence of a citation as proof that every claim in the article was understood. The system itself can make mistakes. Google’s documentation warns that AI Mode can misinterpret web content or miss context. (Google Help)
That is another reason local clarity and explicit evidence matter.
The CITE-to-Citation Pipeline: How a Strong Article Becomes Useful in an AI Answer
The CITE Framework explains what to improve inside the article. The second framework—the CITE-to-Citation Pipeline—explains what happens conceptually between a user’s question and the moment a source becomes part of an answer.
A person begins with a question that may be simple, ambiguous, or highly specific. The system then has to determine what information is needed, discover potentially relevant sources, retrieve useful passages, evaluate how those passages relate to the question, reconcile them with other evidence, and decide how the resulting answer should be presented. The publisher cannot directly control each stage, but the publisher can influence how well the article performs at several of them.
This is why “citation optimization” is a misleading phrase when treated as a promise. A publisher cannot simply place a sentence in a format and cause a model to cite it. What the publisher can do is increase the likelihood that the page contains relevant, understandable, supportable information that survives retrieval and comparison.
Imagine an article about a software pricing model. A useful passage might state the pricing mechanism, give the actual pricing source, explain what counts as billable usage, distinguish fixed from variable costs, and note the conditions under which the published price does not represent total cost of ownership. That passage is valuable because it remains meaningful even when extracted from the article’s larger context.
Now compare that with a vague sentence such as, “This pricing model can be expensive for large teams.” The sentence may be true, but it provides little standalone utility. Expensive compared with what? Why? Under which usage pattern? What evidence supports it? A retrieval system that encounters the sentence has very little to work with.
This is what the pipeline reveals: retrieval value is partly a function of information completeness at the passage level.
What Most AI-Search Optimization Guides Get Wrong
The first major mistake is pretending that every AI platform has a stable public ranking formula. It does not. The official documentation currently available from Google, OpenAI, Perplexity, and Gemini provides useful technical and product guidance, but it does not support the sweeping claim that a particular heading pattern, paragraph length, keyword density, or FAQ structure guarantees AI visibility. Google explicitly says there are no additional AI-search requirements beyond foundational SEO, while OpenAI says placement is not guaranteed.
The second mistake is confusing structured content with fragmented content. An article does not become more extractable simply because every sentence sits in its own block. In fact, splitting related ideas into dozens of tiny fragments can remove context and make the article feel artificial. Extractability should come from clear information architecture, not from destroying editorial prose.
The third mistake is assuming that more entities and keywords automatically create stronger topical authority. A page can mention every relevant concept in the industry and still fail because it does not explain the relationships among them. Topical coverage is not a vocabulary contest. The article needs enough conceptual depth to answer the important questions that arise from the topic.
The fourth mistake is using citations as decorations. Ten outbound links do not automatically make an article trustworthy. The sources have to be relevant, authoritative for the claim, and connected clearly to the conclusion being drawn.
The fifth mistake is mass-producing AI-written pages in the hope that sheer volume creates visibility. More pages can mean more opportunities, but it can also mean more repetitive information, weaker internal architecture, maintenance debt, and increased risk of publishing claims that are difficult to verify. The better strategy is to create fewer, stronger resources where the information gain is obvious.
The sixth mistake is treating AI search as the death of traditional SEO. Google’s own documentation directly contradicts that framing. The normal technical and content foundations remain relevant to its AI features. AI search changes the information journey; it does not eliminate the underlying need for accessible, useful web content.
The Hard Truth: Better Formatting Cannot Rescue Weak Information
There is a temptation in every emerging search environment to look for a shortcut. Publishers want the equivalent of the old keyword-density playbook: a simple rule they can apply to every page and expect visibility in return.
AI search is unlikely to remain that simple because the underlying problem is not just retrieval. It is evidence selection and answer construction.
If your page repeats common industry claims, contains no original insight, offers little evidence, and gives generic recommendations that could have been written by hundreds of competitors, a cleaner heading structure will not suddenly turn it into a preferred source. It may help a system interpret the page, but interpretation is not the same thing as value.
That is why the strongest advantage remains original information.
A publisher who documents a real workflow has something competitors cannot perfectly duplicate. A publisher who performs an honest comparison under clearly stated criteria has created a useful decision asset. A publisher who calculates total cost using transparent assumptions has created evidence. A publisher who documents where a popular strategy fails has created information that helps readers avoid mistakes.
Those are durable advantages because they live in the content itself, not in the presentation layer.
Who Should Invest Heavily in AI-Search Optimization?
The strategy is especially valuable for publishers whose content is designed to influence decisions rather than merely attract impressions. That includes SaaS companies, affiliate publishers, specialist blogs, agencies, B2B publishers, education sites, and independent creators whose articles answer questions with enough depth to earn repeated reference.
It is particularly useful when the subject involves comparisons, implementation decisions, research, troubleshooting, product selection, or rapidly changing information. These are the environments where a synthesized answer can replace several conventional searches, making the quality of the underlying sources more consequential.
On the other hand, a publisher should not spend weeks engineering a sophisticated AI-search framework around a page that has no useful information to begin with. If the article is a thin summary of a commodity topic, the first investment should be better substance, not better extraction.
Likewise, very small publishers should not confuse AI-search optimization with an obligation to publish hundreds of pages. A smaller library of highly useful, strongly connected articles can be more strategically valuable than a large archive of near-duplicate content.
Who Should Avoid Over-Optimizing for AI Search?
Avoid over-optimization when the content begins to sound as though a machine wrote it for another machine.
That usually happens when the author becomes obsessed with forcing every paragraph to begin with an answer, inserting keywords into unnatural places, turning every concept into a miniature FAQ, or writing in a sequence of disconnected declarations. The resulting page may look “optimized” in a screenshot and become significantly worse to read.
The deeper danger is that optimization itself becomes the editorial objective. Once that happens, publishers start producing pages to satisfy a hypothetical scoring system rather than to satisfy readers.
The correct priority remains the same: information quality first, accessibility second, platform-specific considerations third.
That hierarchy also protects against changes in AI interfaces. When the interface changes, the publisher does not have to rebuild the intellectual foundation from scratch.
A Practical AI Search Audit for Any Existing Blog Post
A useful audit should begin with five questions.
| Area | Audit Question | What Good Looks Like |
|---|---|---|
| Crawlability | Can the relevant search systems access the page? | Crawl allowed, page indexable, important content accessible |
| Intent | Does the article solve one primary user problem? | Clear purpose, relevant depth, minimal intent conflict |
| Evidence | Can consequential claims be verified? | Appropriate sources, transparent calculations, clear claim context |
| Extractability | Can important ideas be understood from relevant sections? | Clear definitions, comparisons, procedures, local context |
| Visibility | Can performance and changes be measured? | Search Console, analytics, referral tracking, periodic audits |
The audit should then become more qualitative.
Read only the introduction and first major section. Can you explain what the article is trying to accomplish? Next, open a random middle section. Can you understand its main point without rereading half the article? Find the three most important claims. Can you identify the evidence or reasoning behind each one? Look at the recommendations. What criteria produced them? Finally, inspect the parts most likely to become outdated. Which facts need periodic maintenance?
That process exposes weaknesses that keyword tools often miss.
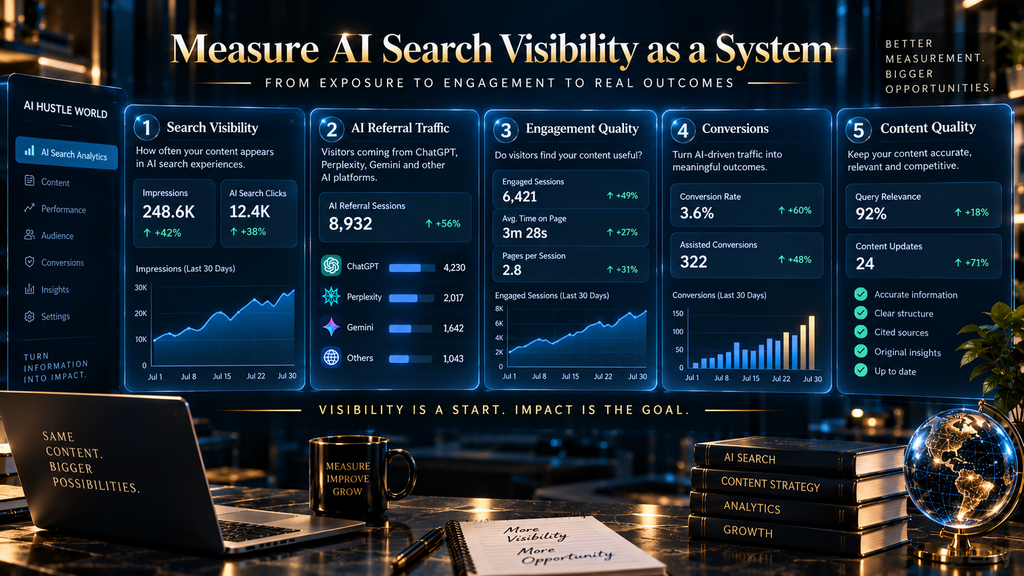
How to Measure Whether the Rewrite Actually Improved the Article
Measurement should follow the objective of the page. A how-to guide may care about organic impressions, relevant clicks, engaged sessions, assisted conversions, and repeat readership. A commercial comparison may care more heavily about qualified traffic, product-page clicks, affiliate conversions, and revenue per visitor. A thought-leadership article may place greater value on branded search growth, backlinks, direct traffic, and citations or references from other publications.
For Google Search, Search Console provides the foundational visibility layer, including performance reporting for AI-feature exposure within the overall web search reporting framework. For ChatGPT referrals, the documented utm_source=chatgpt.com parameter can help isolate traffic originating from ChatGPT Search.
But measurement should not stop at traffic. Look at query quality and conversion quality. If a page attracts fewer visitors but those visitors are substantially more relevant, spend more time engaging with the site, or convert at a higher rate, the optimization may have improved business value even if total sessions barely move.
Also measure the information itself. After a major revision, ask whether the article contains more original material, more defensible claims, clearer decision criteria, better examples, and stronger local context. Those are editorial improvements even before the search graphs respond.
This matters because search systems can take time to respond to meaningful content changes, and because no platform promises that better content will automatically receive more visibility. The correct approach is evidence-led iteration rather than instant-score optimization.
What Happens If You Do Nothing?
Ignoring AI-mediated search does not necessarily make a website disappear. Traditional search remains important, and many pages will continue to earn traffic through conventional discovery.
The risk is subtler.
If users increasingly ask complex questions through AI interfaces, the click decision can move upstream. Instead of selecting a page from ten blue links, the user may first encounter a synthesized answer and then decide which supporting sources deserve further investigation. That changes the competitive unit from “which page ranks for this query?” toward a broader question: which sources become part of the answer?
You cannot assume that AI search will replace traditional search, and it would be irresponsible to treat that outcome as settled. But the direction of product development is clear enough to justify adaptation. Google is expanding AI Mode, OpenAI is integrating web search into ChatGPT, and Perplexity is building a source-driven answer environment. These systems still depend heavily on the web as an information layer.
Doing nothing therefore carries an opportunity cost. You may continue to optimize pages for one discovery journey while another discovery journey becomes increasingly important to your audience.
The Second-Order Effect: Content Architecture Becomes More Important
There is a larger consequence to AI search that many publishers have not fully considered: site architecture may matter more because complex questions create relationships among multiple information needs.
Suppose one article explains AI SEO broadly, another explains AEO and GEO terminology, another covers Google AI Overviews, another explains AI keyword research, and another explains how to optimize individual blog posts. Those pages should not exist as disconnected documents that happen to share the same topic.
Each should explain a different layer of the subject and make the relationship among those layers clear where it genuinely helps the reader. That creates a coherent information environment in which the publisher becomes more useful across a topic rather than merely producing isolated keyword targets.
This is particularly important for complex questions because Google’s AI Mode can perform multiple searches across subtopics when generating a response. A well-connected site can therefore offer depth across several related information needs while preserving distinct intent at the page level.
That does not mean creating dozens of thin supporting pages just to manufacture topical authority. The AI Hustle World editorial rule is more demanding: every page must have a distinct purpose and add genuine topical value. When another article would simply repeat the same explanation with a slightly different keyword, the better decision may be to improve the existing resource instead of publishing another URL.
The Future of AI Search Optimization: From Ranking Pages to Building Evidence Assets
The long-term change may be larger than any specific ranking factor.
Traditional content strategy often treated an article as a traffic asset. The primary question was how many people could be brought to the page from search.
In an AI-mediated environment, the article increasingly behaves like an evidence asset. Its value can come from being discovered, quoted, summarized, compared, referenced, linked, or used as supporting evidence inside an answer—even when the user does not experience the full article as the first destination.
That creates new incentives for publishers to invest in material that is difficult to commoditize: transparent methodologies, original data, real case studies, documented workflows, strong editorial standards, and expert interpretation.
The second-order consequence is that low-information content becomes more vulnerable. If ten pages say essentially the same thing, an answer system has little reason to distinguish among them on the basis of substance. The page that adds something materially different has a stronger reason to exist.
That is why the future strategy should not be “produce more AI content.” It should be produce more information that AI systems have a reason to retrieve.
A Decision Framework for Publishers
The following framework can guide how aggressively to optimize a page.
| Situation | Priority |
|---|---|
| Page is thin or generic | Improve original information first |
| Page is excellent but technically inaccessible | Fix crawlability before rewriting |
| Page gets traffic but answers poorly | Rework intent alignment and structure |
| Page makes many unsupported claims | Rebuild evidence architecture |
| Page is comprehensive but hard to navigate | Improve extractability and information hierarchy |
| Page performs well but contains outdated facts | Perform a substantive freshness update |
| Page targets several conflicting intents | Narrow the primary purpose |
| Page is strong and measurable | Iterate based on actual performance |
The key is that not every problem is a writing problem. Sometimes the bottleneck is technical. Sometimes it is editorial. Sometimes it is evidence. Sometimes the page is already good and the correct move is simply to measure, maintain, and strengthen the surrounding topic cluster.
That judgment is more valuable than any universal checklist.
Ten Common Mistakes When Optimizing Blog Posts for AI Search
1. Repeating the Target Keyword Until the Article Sounds Unnatural
Keyword relevance still matters, but repetition does not substitute for topical completeness. The better strategy is to cover the concepts, questions, comparisons, and entities that genuinely belong to the user’s problem.
2. Creating Separate Articles for ChatGPT, Perplexity and Gemini Without a Real Intent Difference
Platform-specific versions often create duplication rather than authority. Build one canonical resource and differentiate pages by user intent, not by the AI interface being discussed.
3. Treating FAQ Sections as a Shortcut to AI Citations
Questions and answers can improve usability, but there is no documented guarantee that adding an FAQ block causes an AI system to cite the page. The answer must still be useful, accurate, and appropriately supported.
4. Adding Schema That Does Not Match the Visible Page
Structured data should describe what is actually on the page. Google specifically recommends that structured data match visible content and does not require special AI schema.
5. Using Vendor Claims as Independent Evidence
A vendor can accurately describe its own feature or pricing. That does not mean its marketing claim should automatically become an independent performance conclusion.
6. Publishing Statistics Without Context
A percentage without a population, timeframe, methodology, baseline, or source can look authoritative while remaining practically meaningless.
7. Mistaking Short Sentences for Extractability
AI-friendly writing is not the same as fragmented writing. Preserve the causal relationships, context, and nuance that make the information actually useful.
8. Ignoring the Site-Level Trust Environment
Authorship, corrections, editorial transparency, and the separation of advertising from editorial content can affect how readers—and some search environments—perceive the source. Perplexity’s source-label documentation explicitly describes site-level review criteria along these lines.
9. Treating AI Search Visibility as Guaranteed
It is not. OpenAI explicitly says placement is not guaranteed, and Google states that meeting best practices does not guarantee crawling, indexing, or serving.
10. Measuring Rankings Instead of Outcomes
A page can gain impressions without gaining meaningful business value. The real objective is better discovery, better relevance, better trust, better engagement, and better decisions—not a prettier dashboard.
Final Thoughts: Build Content That Deserves to Be Retrieved
The most important shift in AI-search optimization is not a new schema, a new keyword strategy, or a clever paragraph format. It is a change in what you consider the unit of value.
A traditional SEO mindset can make a publisher think primarily about ranking a page. An AI-search mindset should add another question: What happens when this page is treated as evidence? Can the important information be found? Can it be understood without the entire article? Can the key claims be verified? Does the article explain something competitors have not explained well? Does it help someone make a better decision?
Those questions lead directly to the AI Hustle World CITE Framework. Crawlability makes the information accessible. Intent Alignment makes it relevant to the actual problem. Traceable Information gives important claims a defensible foundation. Extractability makes the useful ideas understandable and reusable. Verification & Visibility turns the process into something that can be measured and improved.
The contrarian lesson is that AI-search optimization is not really about optimizing for AI. The strongest form of optimization is building an information asset that remains valuable when the search interface changes, when the query becomes more complex, when the system retrieves only one paragraph from the middle of the article, and when a skeptical reader asks, “How do you know that?”
That is the standard worth building around. Not content that merely gets discovered.
Content that gives a retrieval system a reason to trust, use, and reference what it discovers.
Build a Stronger AI Search Strategy
Go deeper into AI SEO, search visibility, keyword research, and the strategies shaping how content gets discovered in modern search.
Read the AI SEO Guide →Frequently Asked Questions
How do I make my blog posts appear in ChatGPT?
Start with normal SEO foundations and make sure the relevant pages can be crawled. OpenAI specifically recommends allowing OAI-SearchBot if you want your public website to be discoverable and surfaced in ChatGPT Search. However, OpenAI also states that search placement is not guaranteed, so crawler access should be treated as an eligibility and discoverability condition rather than a ranking shortcut.
Does ChatGPT SEO require special schema?
There is no official evidence that publishers need a special “ChatGPT schema” to rank in ChatGPT Search. Google likewise says that its own AI Search experiences do not require special AI schema or machine-readable AI files. The more durable strategy is to maintain strong technical accessibility and useful, well-structured content.
How do I optimize content for Perplexity?
Make sure the page is accessible to PerplexityBot and avoid blocking it through robots.txt when discoverability on Perplexity matters to you. Then focus on evidence, source clarity, strong authorship, and useful original information. Perplexity explicitly says its crawler respects robots.txt and its source-review system considers site-level qualities such as corrections and authorship.
Does Perplexity favor websites with a Trusted label?
A Trusted label can provide source context inside Perplexity, but Perplexity explicitly says labels describe the overall website and do not guarantee the accuracy of a particular article or claim. The absence of a label is also not necessarily a negative judgment.
How do I optimize blog posts for Gemini?
Use the foundational SEO and editorial practices recommended for Google Search and its AI features: ensure the page is crawlable and indexable, use clear internal links, make important content available in text, provide useful media where appropriate, and keep structured data accurate. Google does not document a separate secret optimization formula for Gemini-powered search experiences.
Should I write shorter articles for AI search?
Not automatically. Article length should follow the information required by the intent. A page can be long and highly extractable when its information hierarchy is clear. The objective is to make important ideas easy to identify without stripping away evidence, context, and nuance.
Should every paragraph contain a direct answer?
No. Answer-first writing is useful for major sections where a concise self-contained statement improves clarity, but forcing every paragraph into that format creates repetitive and unnatural prose. Strong articles alternate between answers, explanation, evidence, examples, interpretation, and practical guidance. AI Hustle World uses answer-first formatting where it is natural while preserving developed editorial prose.
Do backlinks still matter for AI search?
You should not assume that AI search makes traditional authority signals irrelevant. Google explicitly states that foundational SEO remains relevant to its AI features, and strong discoverability still depends on the underlying web ecosystem. What has changed is that visibility can involve more than a conventional ranked click, so publishers should think about authority, evidence, relevance, and citation potential together rather than treating backlinks as the only measure of authority.
Can AI-generated content rank in AI search?
The existence of AI-generated text does not itself determine whether a page is useful. The more important question is whether the content contributes meaningful information, satisfies the user’s intent, remains accurate, and provides sufficient originality and evidence. Publishing large volumes of generic AI-written material is not a substitute for information gain.
How often should I update an AI-search-optimized article?
Update it when facts materially change rather than simply changing the publication date. Pricing, product capabilities, platform documentation, statistics, screenshots, examples, and conclusions may need revision as the subject evolves. A substantive update should reflect real changes in the underlying information rather than serving as a cosmetic freshness signal.
Related Guides
- Best AI Tools for Writing Blog Posts (Free & Paid)
- AI SEO vs Traditional SEO: What Actually Matters in 2026?
- How to Use ChatGPT for Blogging: Complete Beginner’s Guide
Written by
Muntasir Ahmad Chowdhury
Founder, AI Hustle World
Muntasir Ahmad Chowdhury is the Founder of AI Hustle World, an independent publication dedicated to making Artificial Intelligence practical, trustworthy, and easy to understand. He researches AI tools, automation, customer service, productivity, and real-world business applications, helping readers make smarter technology decisions through research-driven, experience-backed content.
Expertise:
AI Tools • AI Automation • AI Customer Service • AI Productivity • Generative AI • AI Workflows
Get Smarter With AI
Enjoyed this guide? Get practical AI tools, tutorials, and honest reviews delivered to your inbox.