Evidence: Documentation reviewed
Last checked: September 2026
What was done: Written from official documentation and the published sources linked in this article. Not hands-on tested.
Files: None
Affiliate links: No
AI Lead Scraping Explained: How Businesses Find B2B Prospects at Scale
The internet contains an enormous amount of information about businesses, but having access to that information is not the same as having a useful prospecting system. A salesperson can research a handful of companies by opening websites, reading product pages, checking company information, identifying relevant people, and recording what matters. That approach can work surprisingly well when the target list is small. The economics change completely when a sales organization needs to evaluate thousands of potential accounts every month.
Consider a B2B software company selling to North American businesses with 50 to 500 employees. The company may know its ideal customer profile down to the industry, technology environment, business model, geography, and buyer role. The difficult part is finding enough real companies that satisfy those conditions, determining which information is current, and separating genuinely relevant prospects from businesses that merely look similar on the surface. Manual research becomes a bottleneck because every additional account requires another round of searching, reading, copying, checking, and organizing.
This is the problem AI lead scraping is trying to solve. At its simplest, it combines automated data extraction with AI-assisted processing to discover and organize potential prospects from appropriate sources. But the important part is what happens after the extraction. A scraped record is not automatically a lead, and a lead is not automatically a qualified opportunity. The real value comes from turning scattered information into evidence that a sales team can trust and act on.
That distinction changes how the entire category should be evaluated. The impressive number is not how many records a scraper can produce. The useful number is how many relevant, sufficiently accurate, current, and actionable prospects the system can produce without consuming an unreasonable amount of human effort.
Quick Answer: What Is AI Lead Scraping?
AI lead scraping is the use of automated extraction and AI-assisted analysis to discover, structure, classify, and organize information about potential B2B prospects from appropriate data sources. Traditional scraping is usually concerned with extracting defined fields from webpages or databases, while AI-assisted systems can also interpret information that is expressed in less predictable language, classify companies, summarize evidence, and help determine whether a candidate appears relevant to a particular ideal customer profile.
The distinction is important because AI does not turn scraping into a magic lead-generation machine. It can help a system understand that a company appears to sell enterprise software, serves healthcare organizations, uses a particular technology, or is expanding into a new market. But those conclusions are still based on evidence that may be incomplete, outdated, ambiguous, or incorrectly interpreted. A responsible workflow therefore treats AI as an interpretation and prioritization layer, not as an automatic source of truth.
The most useful mental model is to think of AI lead scraping as the beginning of a prospect-data pipeline: discover information, extract it, structure it, resolve identities, verify important facts, enrich the record, interpret the evidence, prioritize the candidate, and only then move it into a sales workflow. Scraping is one part of that chain. The downstream stages determine whether the information becomes commercially useful.
The Problem AI Lead Scraping Is Actually Solving
The appeal of lead scraping is often described as “saving time,” but that explanation is too shallow. The deeper problem is that modern B2B prospecting involves a large amount of information-processing work that sits between knowing who you want to sell to and actually having a useful conversation with them.
A salesperson might begin with a list of companies and then open each website to understand what the business does. They may inspect the company’s products, industries served, locations, leadership team, hiring activity, technology environment, customer examples, and recent announcements. They then have to decide whether the company actually fits the ICP, find the appropriate role, check whether the information is current, enter the relevant details into a CRM, and repeat the process for the next account. None of those individual actions is particularly difficult. The problem is the repetition.
At ten minutes per account, researching 10,000 companies would require roughly 1,667 hours of work. That calculation is illustrative rather than a universal productivity benchmark, because real research times vary significantly by company and use case, but it demonstrates the structural problem: when the prospect universe becomes large, human attention becomes the scarce resource.
Automation changes that equation by taking over repetitive discovery and organization. The objective should not be to remove human judgment from prospecting. It should be to reserve human judgment for the parts of prospecting where judgment actually creates value.
That is the first principle behind useful AI lead scraping: automate information handling before you automate business judgment.
AI Lead Scraping Is Not the Same as Web Scraping, Enrichment, or Lead Qualification
A large amount of confusion around AI prospecting comes from treating several different activities as if they were one process. They are connected, but each solves a different problem.
Web crawling is primarily about discovering pages or navigating through a source. Web scraping is about extracting information from those pages. Parsing turns that extracted information into a structured representation that another system can work with. Lead scraping applies those techniques specifically to the discovery of potential sales prospects.
The process becomes more valuable, and more complicated, after extraction. Enrichment adds additional information to an existing record. Qualification evaluates whether the prospect meets the business’s criteria. Buying-signal analysis asks whether there is evidence that the company may have a reason to buy now. Outreach is the actual communication process.
Those distinctions matter because each stage has a different success criterion. A scraper can be excellent at extraction while being terrible at qualification. An enrichment provider can add hundreds of fields without making a record more relevant. An AI classifier can identify an apparent ICP match while being wrong about the underlying company. A sales team that treats all of these activities as one “lead-generation” step will have difficulty identifying where its process is actually failing.
A useful way to frame the progression is this: crawling finds where information may exist; scraping extracts it; structuring makes it usable; enrichment adds context; qualification evaluates fit; buying-signal analysis evaluates timing; and sales execution decides what to do with the result. The more clearly those responsibilities are separated, the easier the entire system becomes to measure and improve.
What AI Changes About Traditional Lead Scraping
Traditional scraping works extremely well when the information is predictable. If a directory consistently places the company name, website, location, and phone number in the same fields, a deterministic extraction process can collect that information quickly and repeatedly. There is no particular reason to use an AI model for every predictable field simply because AI is available.
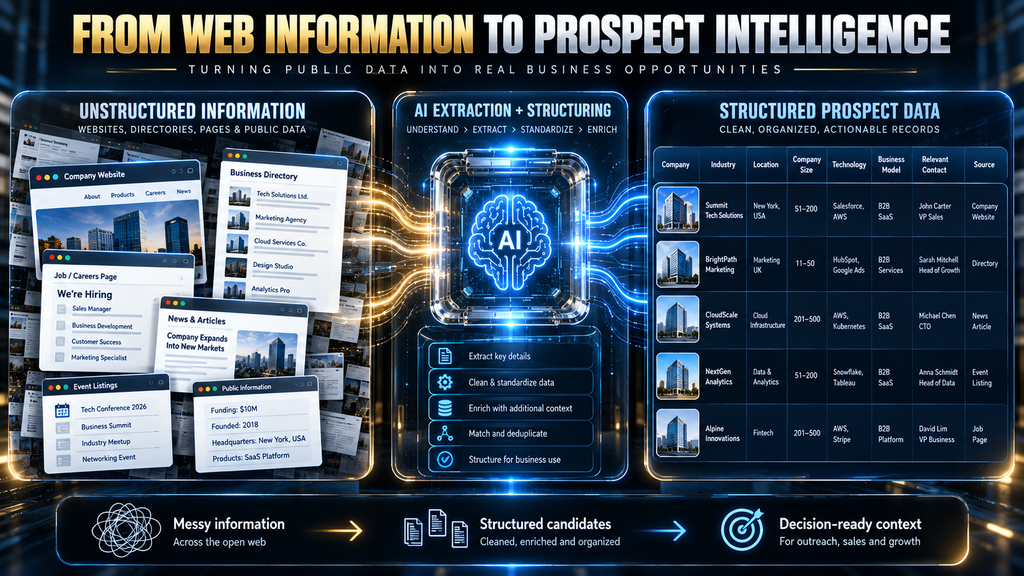
The harder problem appears when the information required for prospecting is embedded in natural language and scattered across different parts of a website. A company may never explicitly state, “We are a mid-market B2B SaaS company targeting healthcare organizations and currently expanding our sales team.” Instead, the evidence may be distributed across its homepage, product pages, customer stories, careers section, press releases, and other public business information.
AI can help bridge that semantic gap. Rather than asking only, “Where is the employee-count field?”, a system can potentially interpret several pieces of information and determine what the business appears to do, which market it serves, what kind of customer it targets, and whether certain contextual signals are present.
That does not make AI inherently better than deterministic extraction. In fact, using AI for simple, highly structured tasks can introduce unnecessary cost, latency, and variability. The stronger architecture is usually hybrid: conventional automation handles predictable operations, while AI is introduced where interpretation, classification, summarization, or contextual reasoning is genuinely useful.
This is one of the most important practical conclusions in the entire topic. The best AI lead-scraping system is not the one that uses the most AI. It is the one that uses AI precisely where deterministic methods stop being sufficient.
The Prospect Data Value Chain
The most useful way to understand AI lead scraping is as a chain of transformations rather than a single scraping event.
A prospect usually begins as scattered information: a webpage, directory listing, business announcement, event profile, company description, or another permitted source. The first job is to discover that information. The second is to extract what matters. From there, the system has to turn inconsistent information into a structured record, determine which real-world company the record belongs to, verify important facts, enrich the record where necessary, interpret the evidence, and decide whether the candidate deserves attention.
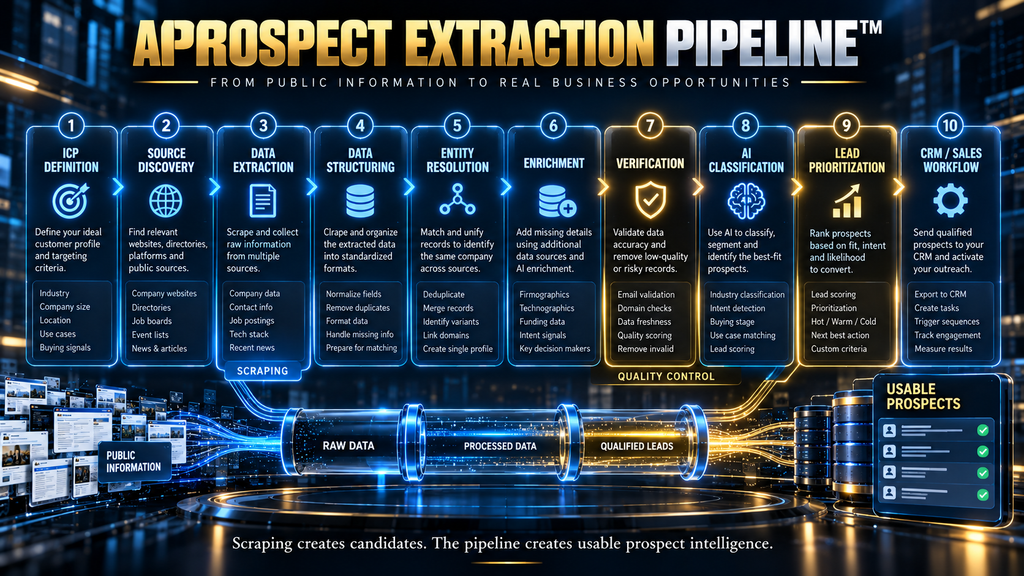
This creates the Prospect Data Value Chain: Discover → Extract → Structure → Resolve → Verify → Enrich → Interpret → Prioritize → Activate.
The sequence is more important than the terminology. If discovery is poor, the system begins with the wrong candidates. If extraction is inaccurate, the record is compromised before AI ever sees it. If entity resolution fails, information can be attached to the wrong company. If verification is skipped, stale or incorrect information can move into the CRM. If prioritization is weak, the sales team simply receives a larger version of the same workload it was trying to escape.
The chain also explains why measuring a scraper by record count is misleading. A system that generates 500,000 raw candidates but produces only a small number of reliable, relevant prospects may be less useful than a smaller system that consistently produces decision-ready accounts.
The commercial objective is therefore not maximum extraction. It is maximum useful information per unit of human attention.
How AI Lead Scraping Works in Practice
Start With the ICP, Not the Scraper
The most common conceptual mistake in automated prospecting is starting with the technology. A team chooses a scraping platform, connects a few sources, and then asks what it can collect. That reverses the logic of the problem.
The first question should be: What makes a company worth pursuing?
Suppose the target is B2B SaaS companies in North America with 50–500 employees. That is already more useful than “B2B companies,” but it may still be insufficient. The sales team may actually perform best when those companies use a particular technology stack, sell to a particular customer segment, have a recurring-revenue model, and show evidence of recent expansion.
The ICP can therefore contain both relatively stable characteristics and contextual conditions. Company size, industry, geography, and business model might define the baseline. Hiring activity, expansion, new product launches, market entry, or changes in leadership might affect prioritization.
This distinction matters because scraping criteria and qualification criteria do not have to be identical. Discovery can remain relatively broad while later stages narrow the candidate universe. Trying to make the first scrape produce only perfect prospects often makes the system unnecessarily rigid.
A good workflow begins with a clear definition of the target and then asks which sources can provide the evidence required to identify that target.
Choose Sources Based on the Decision You Need to Make
There is no universally superior source for B2B prospect discovery. A company website may be excellent for understanding what a business actually sells, while an industry directory may be better for discovering a broad universe of companies. An event exhibitor page may reveal organizations actively participating in a particular market, while a public corporate source may provide more formal business information.
The source should therefore be chosen according to the question the prospecting system needs to answer.
If the question is “Which companies operate in this market?”, broad directories may be useful. If the question is “What does this company actually do?”, its own website may provide stronger context. If the question is “What changed recently?”, company announcements, careers pages, public filings, or other current sources may be more relevant.
This is also where first-party data deserves more attention than it often receives. A company’s own CRM, inbound leads, event registrations, customer database, website submissions, and other internal information may be easier to govern and more directly connected to the business than a large external scraping operation.
The objective is not to collect the maximum number of sources. It is to assemble a source set that provides enough reliable evidence to support the decisions the sales team needs to make.
Public Information Does Not Automatically Mean Permission to Scrape It
This is where a technically attractive workflow can become strategically careless.
A webpage being visible to a person through a browser does not automatically mean that the information can be collected through any automated method, stored indefinitely, combined with other datasets, or used for any commercial purpose. The relevant considerations can include source terms, access restrictions, privacy obligations, intellectual-property considerations, contractual limitations, jurisdiction, and intended use.
LinkedIn is a particularly clear example. Its current User Agreement prohibits users from developing or using software, scripts, robots, crawlers, browser plugins, or other processes to scrape or copy its services, including profiles and other data, and also prohibits unauthorized automated access methods. LinkedIn’s API terms separately restrict access to content obtained through scraping, crawling, or similar methods outside its APIs. (LinkedIn)
That means a responsible prospecting workflow should not be built around the assumption that any publicly visible profile is automatically available for automated extraction. If a source restricts the collection method, the answer is not to design a cleverer way around the restriction. The better options are an authorized access method, a permitted source, or a different data strategy.
The same principle applies to personal data and direct marketing. The UK’s Information Commissioner’s Office notes that B2B marketing can still involve personal-data obligations when information identifies individuals, and it specifically warns that the fact that personal information is publicly available does not by itself mean it can simply be used for direct marketing without considering applicable requirements. (ICO)
The practical rule is straightforward: visibility is not the same thing as permission.
Build a Candidate Universe Before Trying to Find Perfect Leads
Once the target and source strategy are defined, the discovery layer can begin identifying potential companies.
This stage should be deliberately broader than final qualification. Imagine a company wants to identify U.S. cybersecurity businesses with 100–1,000 employees. The discovery system might collect candidate organizations from several relevant directories, company websites, industry sources, event pages, and other appropriate sources. At this point, the objective is not to declare every candidate sales-ready. It is to create a sufficiently broad universe from which better decisions can be made later.
This is essentially a funnel. Discovery creates breadth; subsequent stages create precision.
That distinction becomes important when teams evaluate automation. If a discovery system is judged entirely by how many “qualified leads” it produces, there is a temptation to make aggressive assumptions early in the process. That can increase false positives and cause valuable candidates to disappear before they have been properly researched.
A better architecture allows the early stage to tolerate some uncertainty while making the later stages progressively stricter.
Extract the Information That Can Change a Decision
Once candidate companies have been discovered, the system needs to extract the information that matters.
This sounds obvious, but it is one of the easiest places to create waste. Modern scraping systems can collect enormous amounts of information, and the temptation is to capture everything because storage is relatively cheap. Yet a large dataset is not automatically a useful dataset.
If employee count affects ICP qualification, collect it. If technology environment determines product compatibility, collect the relevant technology evidence. If customer segment matters, collect the information that can support that classification. If a company’s recent expansion is a meaningful buying context, collect evidence related to expansion rather than dozens of unrelated fields.
The principle is simple: a field earns its place in the dataset when it can change a decision.
AI becomes useful when the relevant information does not appear in a neat field. A company might say that it “helps healthcare organizations secure cloud workloads.” From that description, an AI-assisted extraction process could potentially identify the business as a cybersecurity provider serving healthcare organizations with a cloud-security offering. Those classifications are useful, but they should remain connected to the evidence that produced them.
That last point is crucial. A classification without its supporting evidence is difficult to audit and difficult to correct.
Turn Messy Information Into Structured Business Data
Web information is written for humans, not databases. One company may describe its workforce as “250 employees,” another may say “a team of more than two hundred,” and another may place the information inside a company profile that uses a range rather than a precise number.
A prospecting system needs to normalize those variations into fields that can be compared consistently. The same principle applies to industry categories, business models, locations, technologies, customer segments, and job titles.
This is where parsing and AI-assisted structuring complement each other. Deterministic rules are often excellent when the format is predictable. AI can help interpret language when the same underlying concept appears in many different forms.
But normalization should not erase the original evidence. A strong record can contain both the structured value and the source context that supports it. That allows the system to benefit from machine-readable data without losing the ability to inspect where the conclusion came from.
The difference may seem minor when looking at one record. At scale, it becomes a major quality-control mechanism.
Resolve the Real-World Entity Before You Trust the Record
Entity resolution is one of the least glamorous parts of prospect data and one of the most consequential.
Suppose the system discovers “Acme Analytics.” Is that the correct company? There may be several businesses with similar names, a parent organization with multiple brands, a subsidiary operating under a different legal name, or a company that has recently changed its domain. The same problem becomes even more difficult when identifying people with common names.
The system may therefore need to compare multiple pieces of evidence, such as company name, domain, geography, industry, address, existing CRM records, and other identifiers. The goal is not merely to match strings. It is to determine whether the information refers to the same real-world entity.
This matters because incorrect information can be more dangerous than missing information. Missing data tells a salesperson that something is unknown. A confidently wrong record can cause the salesperson to act on false information while believing the database has already done the research.
For that reason, entity resolution should be treated as a core component of prospecting infrastructure rather than a cleanup task that happens after everything else.
Scraping Creates the Record; Enrichment Expands It
Once the basic identity of the candidate is established, enrichment can add the context required for more useful decisions.
A scraped record might tell you that a company exists, where its website is located, what it says about its business, and perhaps which publicly listed roles are relevant. Enrichment can add additional firmographic, technological, geographic, or business context from appropriate sources.
The distinction is important because scraping and enrichment solve different problems. Scraping is primarily concerned with discovering or extracting information from the chosen source. Enrichment expands an existing record with information that was not available in the initial extraction or that needs to be obtained from another source.
Keeping those stages conceptually separate also improves troubleshooting. If the company identity is wrong, the problem may be in discovery or entity resolution. If the company identity is correct but its employee count is wrong, the problem may be in enrichment or verification. If the data is accurate but the company should never have been targeted, the problem may be the ICP or qualification model.
A good system makes those failure points visible rather than treating the entire process as one opaque “AI lead-generation” operation.
Verification Is Where a Candidate Starts Becoming Trustworthy
Extraction does not equal truth.
A scraper can accurately copy an outdated webpage. An AI model can accurately interpret a sentence that was written two years ago. A database can contain a correct job title that no longer reflects the person’s current role. None of these situations means the extraction process failed technically. They mean the information itself is no longer sufficiently reliable for the intended decision.
Verification should therefore focus on the fields that matter most.
For high-impact information, a second source can increase confidence. A company website might support the company’s identity and product description, while another reputable source may support a firmographic attribute. A recent company announcement may provide stronger evidence of a business change than an older directory listing.
The objective is not to verify every field against five sources. That would simply move the scalability problem from scraping to verification. The smarter approach is to increase verification effort according to the consequence of being wrong.
If a minor descriptive field is wrong, the commercial damage may be negligible. If an incorrect identity or contact detail causes a sales representative to approach the wrong person, the cost can be much higher.
Verification should therefore be proportional to decision risk.
AI Should Interpret Evidence, Not Manufacture It
This is one of the most important principles in AI-assisted prospecting.
AI is particularly useful when a system needs to classify, summarize, compare, or interpret information. But those outputs should remain connected to evidence. If an AI system says that a company is a strong ICP match, the useful question is not merely whether the label says “strong fit.” The useful question is why the system reached that conclusion.
A more defensible output might contain three components: the conclusion, the evidence supporting it, and the confidence level associated with the interpretation.
For example, a prospecting system might determine that a company appears to be a strong fit because its website describes a B2B software product, its reported company size falls within the target range, and its stated customer segment matches the ICP. That is much more useful than a database field that simply says “ICP = Yes.”
The same principle applies to buying signals. If a system claims that a company is evaluating a new CRM, the business should be able to identify the evidence behind that conclusion. Without evidence, the AI output should be treated as an unverified hypothesis rather than a fact.
This distinction becomes increasingly important as AI moves deeper into sales workflows. An incorrect summary in a research document is inconvenient. An unsupported conclusion that automatically changes account priority or triggers outreach can create a much larger problem.
Prioritization Is More Valuable Than Producing Another Giant List
Imagine the scraping system has successfully produced 50,000 candidate records. That sounds like a major achievement until the sales team opens the database and asks the obvious question: Which 500 should we look at first? This is where prioritization becomes more important than raw extraction volume.
A useful prioritization model might consider ICP fit, data quality, business relevance, recency, and contextual evidence. The exact weighting should depend on the company’s sales model. An enterprise seller may value company fit and business context more heavily than a high-volume SMB seller. A technology-specific product may put greater weight on technology compatibility. A time-sensitive offer may place greater emphasis on recent business changes.
The important thing is that the scoring system should represent an actual business decision rather than simply becoming an arbitrary AI-generated number.
A score of 87 is not inherently meaningful. It becomes meaningful only when the organization knows what the score represents, what evidence influences it, and what action should follow from different score ranges.
The purpose of prioritization is therefore not to create a sophisticated-looking ranking. It is to reduce the amount of low-value decision-making that salespeople have to perform manually.
The Lead Data Reliability Model: Accuracy, Freshness, and Provenance
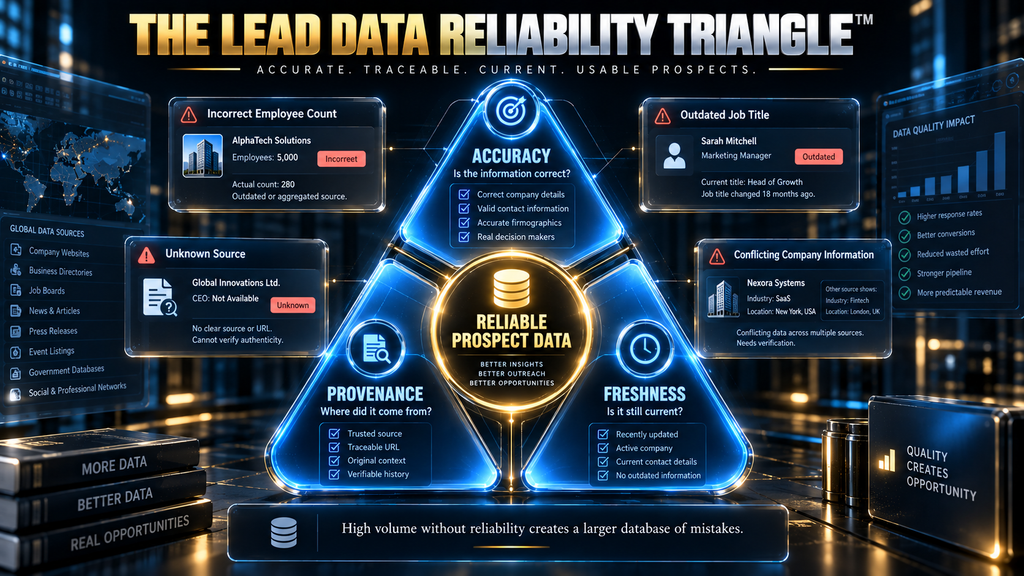
A prospect record can fail in three fundamentally different ways. It can be inaccurate: the information is wrong. It can be stale: the information may once have been correct but is no longer current.
Or it can have weak provenance: the business cannot determine where the information came from, when it was observed, or how confidently it should be trusted. These dimensions interact.
A record with strong accuracy but unknown provenance may be difficult to audit. A record with clear provenance but outdated information may no longer be useful. A record that appears fresh but has questionable accuracy can actively mislead the sales team.
The strongest prospecting records therefore maintain a relationship between the information itself and its source context. Where practical, the system should know what was observed, where it came from, when it was collected or verified, and whether the information was directly stated or inferred.
That is a much more mature definition of “data quality” than simply counting how many fields are filled in. A database can be 98% complete and still be commercially poor.
Traditional Scraping vs. AI-Assisted Scraping
The choice between traditional and AI-assisted scraping should not be framed as a contest in which AI automatically wins.
Traditional extraction remains extremely strong for predictable information. If the task is to collect a company name from a standardized directory 100,000 times, deterministic automation may be faster, cheaper, and more consistent than sending every page through an AI model.
AI becomes more valuable when the task requires semantic interpretation. It can help identify concepts that are expressed differently across sources, classify business models, summarize company descriptions, interpret contextual signals, and answer research questions that cannot be solved reliably by looking for one fixed HTML field.
The trade-off is that AI introduces additional uncertainty. A deterministic parser generally behaves predictably when its rules match the input. An AI system can be more flexible, but it can also produce an incorrect interpretation that sounds plausible.
That means AI-assisted scraping often requires more thoughtful validation, not less.
| Capability | Traditional automation | AI-assisted approach |
|---|---|---|
| Predictable fields | Excellent | Excellent |
| Structured directories | Excellent | Strong |
| Unstructured text | Limited | Stronger |
| Semantic classification | Rule-based | AI-assisted |
| Summarization | Limited | Strong |
| Context interpretation | Limited | Stronger |
| Determinism | Higher | Lower |
| Adaptability | Lower | Higher |
| Hallucination risk | Lower | Higher |
| Need for validation | Important | Very important |
The practical conclusion is not “replace scraping with AI.” It is combine deterministic automation, AI interpretation, and verification according to the nature of the task.
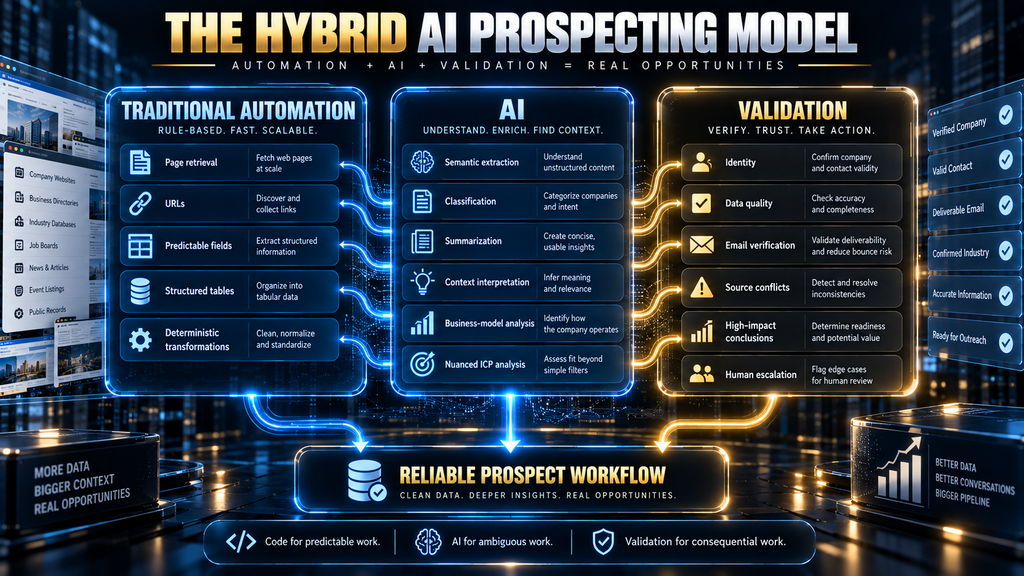
The Hybrid Prospecting Model Is Usually the Stronger Architecture
The strongest systems tend to divide responsibilities instead of asking one technology to do everything.
Traditional automation is well suited to retrieving URLs, processing predictable page structures, extracting fixed fields, parsing structured tables, and performing deterministic transformations. AI is better suited to semantic extraction, classification, summarization, contextual interpretation, business-model analysis, and research questions that require flexible language understanding.
Validation sits between those capabilities and commercial action. It should focus on identity, critical contact information, conflicting records, and high-impact conclusions.
That produces a more rational architecture:
Automation handles predictable work. AI handles ambiguous information. Validation handles consequential decisions. Humans handle judgment that remains difficult to formalize.
This is less exciting than the idea of a fully autonomous sales machine, but it is considerably more practical.
A business does not need an AI model deciding every field in a database. It needs the right technology performing the right job.
Where AI Lead Scraping Works Best
AI lead scraping is most useful when the prospect universe is large enough that manual discovery becomes a material bottleneck and the criteria for identifying potential customers are sufficiently repeatable.
A large B2B market with thousands of potential accounts is a natural candidate. So is a business that needs to monitor changes across an existing account universe, identify new companies entering a market, or repeatedly research the same types of organizations.
It is particularly attractive when the information is available across multiple public or licensed sources but is difficult to collect consistently by hand. In those situations, automation can create meaningful leverage because the system can perform the repetitive work continuously while humans review the more consequential decisions.
The economics are different for small, relationship-driven markets. If there are only a few hundred realistic target accounts and each deal is highly valuable, a salesperson may gain more from deep account research than from building a large scraping infrastructure. The cost of missing context may be greater than the cost of manual research.
This is why “Can AI scrape it?” is the wrong first question. The better question is: Does automation create enough additional decision capacity to justify the complexity it introduces?
Where AI Lead Scraping Breaks Down
The technology becomes less useful when the target market is poorly defined.
If a company cannot explain why one account is a good prospect and another is not, an automated system cannot solve that strategic ambiguity. It can only process the ambiguity faster.
The same problem appears when qualification depends heavily on information that is not publicly observable. Organizational politics, internal priorities, personal relationships, strategic intent, and unusual buying circumstances can be difficult to infer reliably from external data.
Data availability also creates a hard boundary. If the information required to make a decision does not exist in accessible and permitted sources, better scraping cannot manufacture it.
There is another subtle failure mode: false confidence. A structured database makes information look more certain than it may actually be. Once an uncertain inference has been converted into a neat field and assigned a score, users can forget that the underlying evidence was ambiguous.
Good prospecting systems therefore need a way to represent uncertainty rather than hiding it.
Scraping vs. Buying B2B Data vs. Manual Research
Businesses considering AI lead scraping often frame the decision as “build or scrape.” That is too narrow. In practice, there are at least three broad approaches: collect and structure the information yourself, purchase or license structured data, or perform research manually.
The right choice depends on the size of the prospect universe, the uniqueness of the information required, how frequently the data changes, and how much control the business wants over the underlying process.
| Situation | Stronger starting point | Reason |
|---|---|---|
| Small, highly targeted market | Manual research | Human context may outweigh automation benefits |
| Large directory with predictable fields | Scraping or structured automation | Repetitive extraction is well suited to automation |
| Large standardized contact universe | Licensed data | Collection and maintenance can be outsourced |
| Unusual/custom prospect attributes | Scraping + enrichment | Standard databases may not contain the required fields |
| Frequently changing contextual information | Automated research | Monitoring can reduce repeated manual work |
| High-value enterprise accounts | Hybrid approach | Automation supports research while humans make final judgments |
| Undefined ICP | Strategy and manual research first | Automation cannot fix unclear targeting |
| Restricted data source | Alternative permitted source or authorized access | Technical accessibility is not the same as permission |
The hybrid model is often the most rational for high-value B2B sales. Automation can discover accounts and assemble evidence, while humans spend their time understanding the accounts where the potential value justifies deeper research.
The point is not to automate everything. The point is to automate the work that is expensive because it is repetitive, not the work that is valuable because it requires judgment.
The Economics of AI Lead Scraping: Volume Is Not the Same as Value
Scraping can look extraordinarily cheap when measured only by the cost of retrieving another record. That metric ignores most of the economic system around the data.
A realistic cost model can include source access, infrastructure, engineering, maintenance, enrichment, verification, quality control, compliance work, human review, CRM operations, and the sales time spent handling bad records. That last component is particularly easy to overlook.
Suppose an automated workflow produces 100,000 candidate records, but a large percentage are poorly matched or require significant manual checking. The organization has not eliminated the research burden. It has moved part of that burden downstream into the sales team’s workflow.
The relevant economic question is therefore not: How cheaply can we scrape 100,000 records? It is: How efficiently can we produce a smaller set of genuinely useful prospect candidates?
That distinction can completely change the preferred architecture. A workflow that produces 10,000 high-quality candidates may be more valuable than one that produces 500,000 weak records, even if the second system has a lower extraction cost.
The useful unit of measurement is not raw data. It is decision-ready prospect capacity.
How to Measure an AI Lead-Scraping System
The easiest metric to report is the number of records produced. It is also one of the easiest metrics to misuse.
A better measurement system follows the data through several layers. At the discovery level, the business can examine how effectively the system identifies candidate companies and how much of the intended market the selected sources appear to cover. At the data-quality level, it can monitor extraction accuracy, duplicate rates, verification rates, freshness, and contactability.
The more meaningful metrics appear further downstream. The organization should understand what proportion of candidates actually match the ICP, how many become qualified accounts, how many progress to meetings or opportunities, and how much the system costs per qualified account or opportunity.
That creates a much stronger KPI hierarchy:
| Level | Useful questions |
|---|---|
| Discovery | Are we finding enough of the right kinds of companies? |
| Data quality | Is the information accurate, current, and traceable? |
| ICP fit | How many candidates actually match our target? |
| Qualification | How many deserve sales attention? |
| Sales outcome | How many produce meetings or opportunities? |
| Economics | What does each qualified account or opportunity cost? |
The most strategically useful north-star metric will vary by business, but cost per qualified opportunity is often far more meaningful than cost per scraped lead because it connects the data process to an actual commercial outcome. A scraping system should therefore be allowed to produce fewer records if those records consistently produce better downstream results.
The Most Common AI Lead-Scraping Mistakes
The first mistake is automating before defining the ICP. When the target market is vague, automation does not create clarity; it simply creates more data.
The second is optimizing for record count. A sales team cannot monetize records merely because they exist. Someone eventually has to evaluate them, prioritize them, and decide what to do.
The third is treating AI classifications as facts. An AI-generated industry, intent signal, business-model classification, or buying hypothesis should be supported by evidence and treated according to its confidence.
The fourth is ignoring freshness. A record can be technically accurate relative to the source while being commercially outdated.
The fifth is using restricted sources as the foundation of the workflow. If a platform prohibits automated collection, building the entire prospecting architecture around circumventing those restrictions creates a fragile business process.
The sixth is sending outreach immediately after discovery. Finding a candidate and deciding to contact that candidate are different decisions. A verification and qualification layer can prevent bad information from reaching real people.
The seventh is collecting information that nobody uses. Every unnecessary field adds processing, maintenance, storage, and potential quality problems without necessarily improving the sales decision.
The eighth is assuming more automation is always better. Sometimes a deterministic rule is superior to an AI model. Sometimes manual research is superior to both. Good architecture is about assigning the right task to the right method.
Is AI Lead Scraping Legal?
There is no single universal answer because legality and compliance depend on the data, source, collection method, jurisdiction, contractual terms, and intended use.
The distinction between business information and personal information is particularly important. The ICO’s current B2B guidance explains that data-protection requirements can still apply when organizations process personal data in a business context, including information such as an individual’s name or business email address. It also notes that organizations using publicly available personal data for direct marketing cannot simply assume that public availability means the individual has agreed to that use. (ICO)
Marketing rules can also apply after the data has been collected. In the United States, the FTC explains that CAN-SPAM applies to commercial email and does not create a blanket B2B exemption; requirements include accurate sender information, non-deceptive subject lines, a physical postal address, and a clear way for recipients to opt out of future marketing messages. (FTC Search)
That means businesses should separate two questions that are often incorrectly merged: Can we technically collect this information? and Are we permitted to collect and use it in this way? Those are not the same question.
For any serious production workflow, businesses should review the applicable source terms, privacy requirements, marketing rules, retention practices, and intended use. Where the legal position depends on a specific jurisdiction or sensitive use case, professional legal advice is more appropriate than a generic article.
How to Build a Responsible AI Lead-Scraping Workflow
The strongest implementation begins with a manual benchmark rather than a scraping tool.
First, research a small sample of accounts manually and document what makes them genuinely useful. This establishes the decision criteria that the automated system is supposed to support. Without that benchmark, it is difficult to tell whether automation has improved prospecting or merely increased data volume.
Next, define the source policy. Decide which sources are appropriate, what collection methods are permitted, which information is necessary, and which sources should not be used. This step is particularly important when external platforms or personal data are involved.
Then build the discovery and extraction layer. Keep predictable tasks deterministic where possible, and introduce AI when the information requires semantic interpretation. The objective should be a structured candidate record that retains meaningful evidence rather than a black-box score.
After extraction, resolve identities and verify high-impact information. Enrich the records where additional context is genuinely useful, then use AI to classify and prioritize candidates. Low-confidence or high-value records can be routed for human review rather than being automatically activated.
Only after those stages should the information move into the sales workflow. The resulting architecture is: ICP → permitted sources → discovery → extraction → structuring → entity resolution → verification → enrichment → AI interpretation → prioritization → human review → sales workflow. This sequence creates an important control point between finding someone and acting on what the system found.
Who Should Use AI Lead Scraping?
AI lead scraping is a strong candidate when the business has a large addressable market, recurring prospect-research requirements, a reasonably defined ICP, and enough structured or semi-structured information available to support discovery.
It is particularly useful when salespeople are spending significant time performing repetitive research that does not require much judgment. In those cases, the automation can increase the amount of prospecting coverage without requiring a proportional increase in manual research hours.
It is less attractive for businesses with very small target markets, extremely high-value relationship-driven sales, or qualification criteria that depend heavily on information unavailable from external sources. In those situations, automation can still support research, but a fully automated prospecting system may add more complexity than value.
There is also a maturity requirement. Companies with weak positioning, unclear ICPs, poor CRM discipline, or no process for acting on new prospects should fix those foundations before investing heavily in scraping infrastructure.
Automation multiplies the quality of the process you already have. It does not automatically repair the process.
The AI Hustle World Reality Check: More Leads Can Make Prospecting Worse
The most attractive promise in AI lead generation is scale. More sources, more records, more contacts, more automated research, more outreach.
But scale is not inherently valuable.
If a salesperson had to manually review every record produced by the system, increasing the number of records could actually make the operation worse. If AI generates thousands of low-confidence classifications, the team may spend more time checking AI output than it previously spent doing the research itself. If poor-quality data flows into outreach, the company can create a larger volume of irrelevant or poorly targeted communication.
The goal should therefore not be to eliminate every manual step. It should be to eliminate manual work that does not deserve human attention.
A salesperson should not have to spend hours copying company descriptions from websites into a spreadsheet. But a salesperson may need to decide whether a strategically important account’s recent expansion represents a meaningful opportunity. AI can prepare the evidence for that decision without pretending it can make every judgment perfectly.
That is the more credible future of AI prospecting.
What Happens If You Keep Prospecting Manually?
Manual prospect research is not obsolete. For small, carefully selected account lists, it can still be the best approach because the human researcher can adapt to unexpected information, notice context that was not anticipated in the original criteria, and build a richer understanding of the account.
The problem arises when the market is large and the research process is repetitive. In that situation, staying entirely manual means accepting a structural ceiling on coverage. The sales team can only investigate as many accounts as its available human hours allow.
That does not mean the answer is automatically to deploy AI lead scraping.
The right response is to identify where the manual process is actually constrained. If the bottleneck is finding candidate companies, automate discovery. If the bottleneck is understanding messy company information, add AI-assisted research. If the bottleneck is qualification, improve the qualification framework. If the bottleneck is sales execution, scraping more data will not solve it.
This is why the best prospecting strategy begins with the bottleneck rather than the tool.
The Future of AI Lead Scraping: From Extraction to Prospect Research
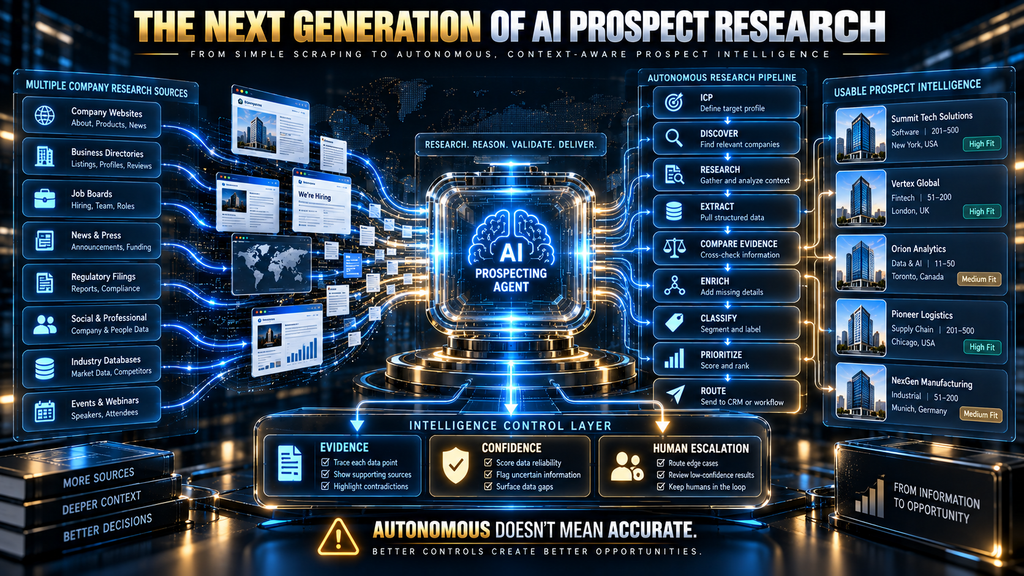
The category is likely to evolve from simple data extraction toward broader AI-assisted prospect research.
The early model was straightforward: find a page, extract a field, save the record. A more advanced system can discover a company, examine multiple sources, assemble evidence, interpret the business context, evaluate potential fit, identify relevant roles, monitor changes, and surface the accounts that deserve attention.
That is a fundamentally different product from a conventional scraper. As extraction becomes increasingly commoditized, the competitive advantage will shift toward better source selection, better entity resolution, stronger evidence handling, more accurate interpretation, better prioritization, and tighter integration with business decisions.
There is also an important second-order effect. The more autonomous prospecting becomes, the more important governance becomes. A human researcher making one incorrect assumption may affect a handful of accounts. An automated system can repeat the same assumption across thousands of records.
That makes provenance, confidence, validation, monitoring, and human review increasingly important as automation improves. The future is therefore unlikely to be “AI replaces prospect researchers.” A more realistic future is AI performs the broad research work while humans spend their time on the decisions where context, consequence, and judgment matter most.
A Practical Decision Framework: Should You Use AI Lead Scraping?
Before building or buying an AI lead-scraping workflow, ask five questions.
First, is the prospect universe large enough to justify automation? If the target market contains only a few hundred meaningful accounts, manual research may be more efficient.
Second, can you define the ICP clearly enough to automate part of the discovery process? If the answer is no, solve the targeting problem before the data problem.
Third, are there appropriate sources that contain the information you actually need? If the critical information is inaccessible, restricted, or simply not published, scraping cannot solve that gap.
Fourth, can you verify the information that matters? If the system will influence sales decisions, important conclusions need an appropriate level of confidence.
Fifth, what happens after the records are produced? If they simply accumulate in a spreadsheet without a clear qualification or sales process, the organization has created a larger database rather than a better prospecting system.
The final question is arguably the most important. A lead-scraping system should be designed backward from the decision it is supposed to improve.
Final Thoughts
AI lead scraping is often presented as a shortcut to unlimited B2B leads, but that framing misses the real opportunity.
The useful transformation is not webpage → contact list. It is scattered information → structured evidence → better prospect decisions.
AI can make that transformation more powerful because it can work with language, context, classification, and messy information in ways that traditional extraction rules cannot. But AI also introduces its own failure modes, which is why evidence, verification, provenance, freshness, and human judgment remain essential.
The businesses that benefit most will not necessarily be the ones that scrape the most sources or generate the largest databases. They will be the ones that build the cleanest path from discovery to trustworthy evidence to commercial action.
That is the real measure of a prospecting system.
A scraped record is a candidate. A useful prospect is an evidence-backed business decision.
Found the Prospects. Now Find the Right Ones.
Scraping can build the candidate universe, but the next challenge is deciding which prospects actually fit your ICP and deserve sales attention.
Explore AI Lead Qualification →Frequently Asked Questions
What is AI lead scraping?
AI lead scraping combines automated data extraction with AI-assisted processing to discover, structure, classify, and organize information about potential B2B prospects. Unlike basic scraping, which primarily extracts predefined fields, AI-assisted workflows can also interpret unstructured information, classify companies, summarize evidence, and help prioritize candidates.
How does AI lead scraping work?
A typical workflow starts by defining the ideal customer profile and identifying appropriate data sources. The system then discovers candidate companies, extracts relevant information, structures the records, resolves company identities, verifies important information, enriches the data where necessary, uses AI to interpret the evidence, and prioritizes candidates for human review or a downstream sales workflow.
Is AI lead scraping the same as lead generation?
No. AI lead scraping is primarily a prospect-discovery and data-processing activity. Lead generation is a broader process that can include market targeting, prospect research, qualification, outreach, inbound acquisition, and conversion. Scraping can support lead generation, but it does not automatically create qualified leads.
What information can AI lead scraping collect?
Depending on the source, collection method, and applicable rules, a system may collect business names, websites, business descriptions, locations, industry information, company characteristics, publicly listed business information, and other relevant signals. The appropriate fields depend on the prospecting objective, and businesses should avoid collecting information simply because it is technically available.
Is scraping LinkedIn allowed?
LinkedIn’s current User Agreement prohibits using software, scripts, robots, crawlers, browser plugins, or similar processes to scrape or copy LinkedIn’s services, including profiles and other data, unless the activity is explicitly permitted. LinkedIn’s API terms also restrict the use of content obtained through scraping or crawling outside its APIs.
Is AI lead scraping legal?
There is no universal yes-or-no answer. The legal and compliance position can depend on the source, data type, collection method, jurisdiction, contractual terms, privacy obligations, and intended use. Public availability does not automatically mean that information can be collected and used for direct marketing without further consideration.
What is the difference between lead scraping and data enrichment?
Lead scraping primarily discovers or extracts information from selected sources. Data enrichment adds additional information or context to an existing record. A prospecting workflow can use both, but they serve different purposes and should be measured separately.
How accurate is AI lead scraping?
Accuracy varies significantly according to the quality and freshness of the sources, the extraction method, entity-resolution process, AI interpretation, and verification system. AI can improve the handling of unstructured information, but it can also produce incorrect interpretations, which is why important outputs should remain connected to evidence and appropriate validation.
How should businesses measure AI lead scraping?
Record volume is only an early-stage metric. More useful measures include extraction accuracy, duplicate rates, verification rates, freshness, ICP-match rate, qualified-account rate, meeting rate, opportunity rate, cost per qualified account, and cost per qualified opportunity. The right north-star metric depends on the business, but downstream commercial quality is generally more useful than raw scrape volume.
Should every business use AI lead scraping?
No. It is most useful when the prospect universe is large, the ICP is reasonably clear, the research process is repetitive, and appropriate sources are available. Smaller markets or highly relationship-driven sales environments may benefit more from manual or hybrid research.
Sources and Further Reading
- Opinion 28/2024 on data protection aspects of AI models: European Data Protection Board opinion on personal data in the context of AI models.
- Legitimate interests: UK Information Commissioner’s Office guidance on relying on legitimate interests as a lawful basis.
Related Guides
- What Is an AI SDR? How AI Agents Automate B2B Prospecting, Outreach & Qualification
- AI Recruiting vs Traditional Recruiting: What Actually Works?
- AI Legal Research: How Lawyers Use AI Without Delegating Legal Judgment
Written by
Muntasir Ahmad Chowdhury
Founder, AI Hustle World
Muntasir Ahmad Chowdhury is the Founder of AI Hustle World, an independent publication dedicated to making Artificial Intelligence practical, trustworthy, and easy to understand. He researches AI tools, automation, customer service, productivity, and real-world business applications, helping readers make smarter technology decisions through research-driven, experience-backed content.
Expertise:
AI Tools • AI Automation • AI Customer Service • AI Productivity • Generative AI • AI Workflows
Get Smarter With AI
Enjoyed this guide? Get practical AI tools, tutorials, and honest reviews delivered to your inbox.