Evidence: Documentation reviewed
Last checked: August 2026
What was done: Written from official documentation and the published sources linked in this article. Not hands-on tested.
Files: None
Affiliate links: No
Last updated: October 2026
How AI Learns From Data: A Complete Beginner’s Guide
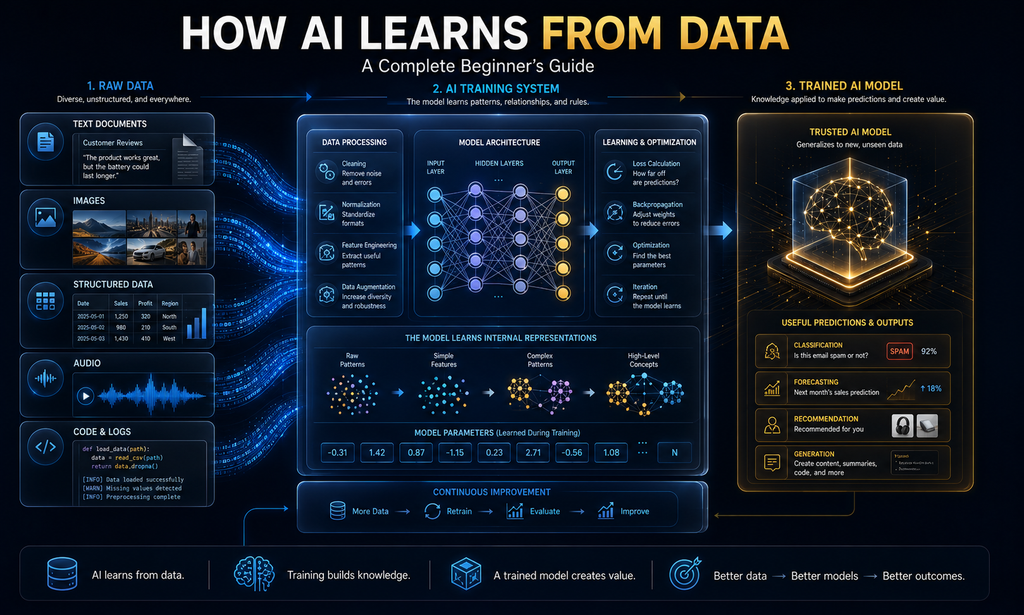
AI learns from data by making predictions, measuring how wrong they are and adjusting millions or billions of internal numbers, called parameters, to make slightly better predictions next time. Repeated across huge numbers of examples, those small adjustments capture patterns in the data, which the model can then apply to new examples it has never seen before.
That is very different from how a person studies. An AI model does not read, understand and remember the way you do. It is a mathematical system tuned by feedback, and what it learns depends entirely on the data it sees, the goal it is given and how its errors are measured. Change any of those, and you change what it learns.
Understanding this process explains a lot about AI behavior: why it can be brilliant on familiar tasks and wrong on unusual ones, why it can absorb bias from historical data, why more data does not always help and why a model that looks excellent in testing can stumble in the real world. It also helps you ask better questions when someone claims their AI is smart.
This guide explains AI learning without math. You will learn what learning means for a machine, the steps of the AI learning loop, the four main learning approaches, how large language models learn, why data quality matters so much, why trained models still make mistakes and how to judge AI claims more intelligently.
Quick Answer: How Does AI Learn From Data?
In the simplest form, an AI model is shown examples, makes a prediction for each one, compares the prediction with the correct answer and adjusts its parameters to reduce the error. After many rounds, the model’s predictions improve, and it can apply what it learned to new cases that were not in its training data.
Modern foundation models follow a longer lifecycle. OpenAI’s help article on how ChatGPT and its foundation models are developed describes using information that is publicly available online, information accessed through partnerships and information that users, human trainers and researchers provide or generate.
The same article says machine learning models consist of large sets of numbers called weights or parameters, and that training adjusts those numbers to reflect patterns in the data. Learning, in other words, is the process of finding parameter values that make the model’s outputs useful for a defined goal.
The rest of this guide unpacks each part of that process: where the data comes from, how errors are measured, how parameters are updated, how models are tested and what can go wrong at each stage, so you can understand both the power and the limits of modern AI. No math is needed to follow along. Each section builds on the last.
What “Learning” Means for a Machine
When people learn, they build understanding, connect ideas to experience and can explain their reasoning. When AI learns, a mathematical model is adjusted so that its outputs improve against an objective, such as predicting the right label or the next word. There is no awareness involved, only numbers being tuned.
That gives a more accurate definition: machine learning is the process of adjusting a model’s parameters so its predictions or outputs get better at a defined task, based on examples. The model does not decide what to learn; the data, the objective and the training method determine it entirely. People shape learning through those choices, not through teaching in the usual sense.
This matters because it explains AI’s strengths and blind spots. A model can become extremely good at a narrow pattern it has seen many times, yet fail completely on a slightly different situation that looks obvious to a person. It learned the pattern in the data, not the underlying idea behind it. That gap between pattern and idea explains many surprising failures.
Keep that framing in mind as you read. Most surprising AI behavior, good and bad, makes sense once you remember that the model is optimizing a numerical goal using whatever patterns in its training data help it do so, including patterns its builders never intended it to use. It is the single most useful idea in this guide.
AI vs Machine Learning vs Deep Learning
Artificial intelligence is the broad goal of making computers perform tasks that usually need human intelligence. Some AI uses hand-written rules, such as a tax calculator or a chess engine with programmed strategies. Those systems do not learn from data; they follow instructions people wrote for them. Rule-based AI is still common in business software.
Machine learning is the part of AI where systems learn patterns from data instead of following only hand-written rules. A spam filter that improves by studying labeled emails is machine learning. Most AI you encounter today, from recommendations to fraud detection, relies on machine learning. It is the engine behind most modern AI products.
Deep learning is a type of machine learning that uses large neural networks with many layers. It powers image recognition, speech recognition and large language models. The free Deep Learning book by Goodfellow, Bengio and Courville is a classic, if technical, introduction. Free online courses also cover the same ideas more gently.
The relationship is nested: deep learning sits inside machine learning, which sits inside AI. Large language models, explained in our guide to what an LLM is, are deep learning models trained on huge amounts of text. Knowing where a tool sits helps you understand its strengths. Most headline AI today is deep learning.
The AI Learning Loop
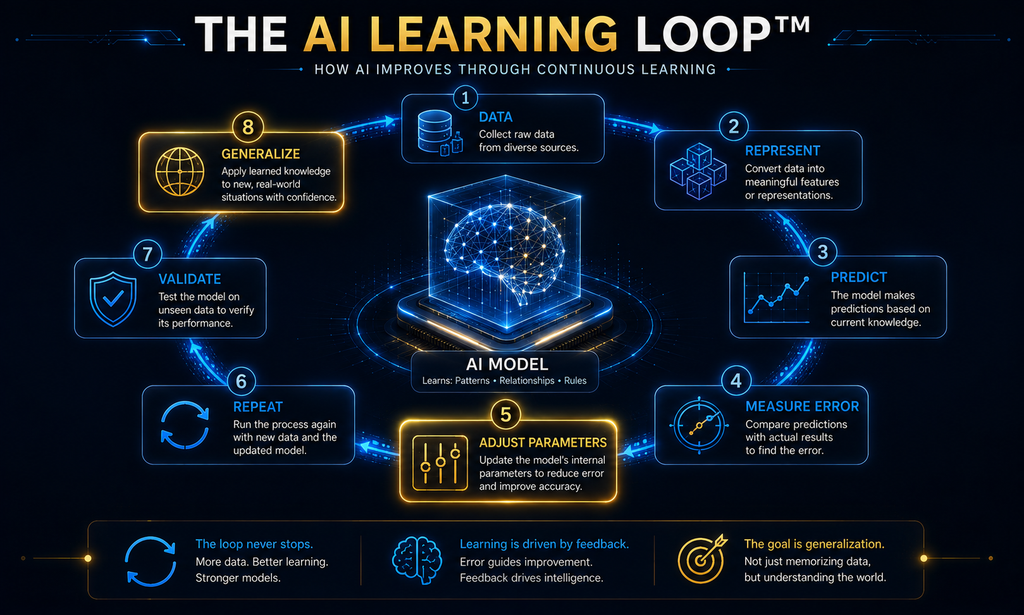
Almost all machine learning follows the same loop, which we will walk through step by step. Data provides examples. The model turns each example into a numerical representation. It makes a prediction. A loss measures how wrong the prediction was. The model updates its parameters to reduce that loss. These five steps repeat millions of times during training.
The loop repeats over many examples and many rounds until the model’s performance stops improving or reaches a target. Then the model is evaluated on data it has never seen, to check whether it learned patterns that generalize rather than memorizing its training examples. Evaluation is the honest check on whether learning worked.
Each step can go right or wrong, and each shapes what the final model can do. Poor data teaches poor patterns. A badly chosen loss rewards the wrong behavior. Weak evaluation hides problems until the model meets the real world. Understanding the loop helps you see where AI systems succeed and where they fail.
Step 1: AI Needs Data
Data is the raw material of learning. For a spam filter, it might be thousands of emails labeled as spam or not spam. For a house-price model, past sales with features such as size, location and age. For a language model, enormous amounts of text from many sources, plus examples written specifically for training.
OpenAI’s help article lists three main sources for its foundation models: public internet information, data accessed through third-party partnerships and information provided or generated by users, human trainers and researchers. It also says the company increasingly uses synthetic data in some training processes.
Data comes in many forms, including text, images, audio, video, numbers and structured records. Whatever the form, it must be collected, cleaned and organized before training. That preparation often takes far more effort than choosing the model itself, and it has a large effect on the result. Teams often spend more time on data than on models.
Why More Data Does Not Automatically Mean Better AI
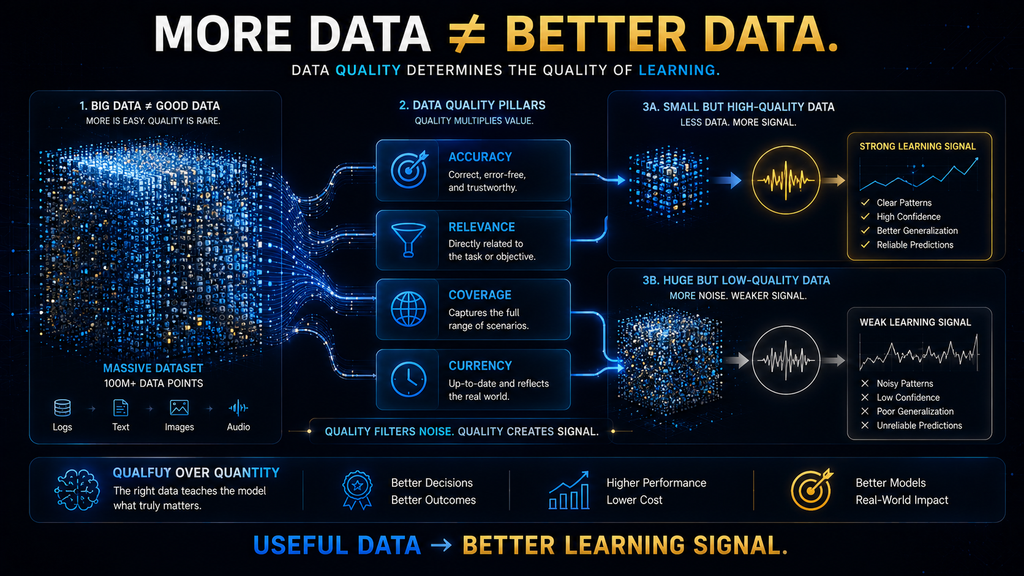
Imagine two fraud datasets. Dataset A has 100 million transactions, but almost all come from one region and one type of customer. Dataset B has 20 million transactions covering many regions, transaction types, customer behaviors, fraud patterns and edge cases. Dataset A is larger, but Dataset B is likely to produce a better model.
That is because a model can only learn patterns that appear in its data. If the data is narrow, the model will be narrow, however large the dataset. If the data contains errors, the model will learn some of those errors. Quantity helps only when it brings real variety and accurate examples. Variety and accuracy matter more than volume.
Research from Stanford supports this. The 2026 AI Index research and development chapter highlights that data quality and post-training techniques are showing promise, and notes that one much smaller model achieved comparable results to a far larger one on several benchmarks through pruning, deduplication and curation alone.
So when someone says their AI is better “because it was trained on more data,” ask what kind of data, how it was cleaned and whether it covers the situations you care about. Those questions often reveal more about likely performance than the raw size of the dataset. Size alone is a weak signal of quality.
What Happens Before Training Begins
Before training, data is cleaned and prepared. Duplicates are removed, errors fixed or filtered, missing values handled and formats standardized. Sensitive information may be removed or protected. For text, harmful or very low-quality content is often filtered out. This work is slow and unglamorous, but it shapes everything that follows.
The data is also split into separate sets for training, validation and testing, which we explain later. And features, the inputs the model uses, may be engineered or transformed, for example converting dates into “day of week” or scaling numbers so they are comparable. These steps help the model focus on useful signals.
Google’s Machine Learning Crash Course dedicates substantial material to working with data, including numerical and categorical data, datasets and generalization. That emphasis reflects reality: most practical machine learning success depends on getting the data right before any training starts. It is a free and practical place to learn more.
Labels: The Teacher’s Answers
Many models learn from labeled examples, where each input comes with the correct answer: this email is spam, this image shows a cat, this transaction was fraudulent. Labels are the teacher’s answers. If they are wrong or inconsistent, the model learns the wrong lessons, however good the algorithm is. Label quality is often the hidden limit on model quality.
Labels are often created by people, which makes them expensive and imperfect. Two reviewers may label the same borderline case differently. Historical labels, such as past hiring or loan decisions, may reflect human bias. And labels can go stale as the world changes, turning yesterday’s correct answer into today’s mistake.
Good teams invest in clear labeling guidelines, check agreement between labelers and review samples regularly. When you evaluate an AI product, asking how its training data was labeled and checked is one of the most revealing questions you can ask, because label quality often sets a ceiling on model quality.
Step 2: Turning Data Into a Representation
Models cannot work directly with words, images or categories. They need numbers. So each input is converted into a numerical representation. An image becomes grids of pixel values. A word or token becomes a list of numbers called an embedding. A customer record becomes numbers for age, spend, location and so on.
Good representations capture what matters. In an embedding, words with similar meanings end up with similar numbers, which lets the model treat “car” and “automobile” as related. Deep learning models also learn their own internal representations, building increasingly abstract features layer by layer. Earlier layers capture simple features, later ones capture more abstract ideas.
This step is why AI can find patterns humans miss: it can compare thousands of numerical features at once. It is also why representation choices matter. If an important factor is not represented, the model cannot use it. Our guide to how embeddings work explains this idea for text. Representation is where raw data becomes something a model can learn from.
Step 3: The Model Makes a Prediction
With a representation in hand, the model makes a prediction using its current parameters. A spam filter outputs a probability that an email is spam. A price model outputs an estimated price. A language model outputs probabilities for the next token. At the start of training, these predictions are close to random.
The prediction comes from passing the input through the model’s layers, a step called the forward pass. Each layer transforms the numbers using its parameters, and the final layer produces the output. The same input always flows through the same path; only the parameter values change as training progresses.
A prediction on its own teaches nothing. Learning happens only when the prediction is compared with the correct answer, which is the job of the next step. That comparison turns each example into feedback the model can learn from. Feedback is the heart of machine learning. Every example becomes a small lesson.
Step 4: Loss Measures How Wrong the Model Was
A loss function gives a single number for how far a prediction is from the target. Google’s machine learning glossary describes loss as a measure of how far a model’s prediction is from its label. Lower loss means predictions closer to the goal. Training is the process of pushing that number down. It is the scoreboard of training.
Different tasks use different loss functions. A price model might measure the squared difference between the predicted and real price. A classifier might measure how much probability it gave to the correct class. A language model measures how much probability it gave to the actual next token. Each loss suits a different kind of prediction.
The choice of loss is a choice about what the model should care about. It defines what “better” means. A loss that ignores rare but important cases will produce a model that ignores them too. That is why defining the objective carefully is one of the most important decisions in any AI project. It deserves careful thought before any training begins.
Step 5: The Model Adjusts Its Parameters
Parameters are the adjustable numbers inside the model, sometimes called weights. A small model may have thousands; a large language model can have billions. Together they determine how inputs are transformed into outputs, and training is the process of finding good values for all of them. More parameters give a model more capacity to learn complex patterns.
After each prediction and loss calculation, the training process nudges parameters slightly in the direction that would have reduced the loss. OpenAI’s help article explains that training adjusts parameters to reflect patterns in the data rather than storing copies of the training examples. Each nudge is tiny, but they add up.
Over millions of small adjustments, the parameters settle into values that work well across the training data. The patterns are spread across all of the parameters rather than stored in any single one, which is part of why it is hard to explain exactly why a large model gives a particular answer. Researchers are still developing tools to explain these patterns.
Step 6: Backpropagation Finds What to Change
With billions of parameters, the training process needs an efficient way to work out how each one contributed to the error. That method is backpropagation. Google’s glossary describes it as the algorithm that implements gradient descent in neural networks. Without it, training large models would be impractical.
In practice, training alternates between a forward pass, where the model makes predictions and calculates loss, and a backward pass, where the error is traced back through the layers to work out how much each parameter should change. The backward pass is what makes training large networks feasible. Modern hardware runs these passes extremely fast.
You do not need the math to grasp the idea. Backpropagation is like tracing a mistake back through a chain of decisions to see which decisions contributed most, then adjusting those the most. It does this automatically and very quickly across every parameter in the model. It is one of the most important ideas in modern AI.
Step 7: Gradient Descent Moves Toward Lower Loss
Once the training process knows which direction each parameter should move, an optimization method updates them. The most common family is gradient descent. Google’s glossary defines it as a technique for minimizing loss by iteratively adjusting weights and biases, gradually finding the best combination.
A helpful picture is walking downhill in fog. You cannot see the lowest point, but you can feel which way the ground slopes under your feet. Each step goes slightly downhill. Repeat enough times, and you reach a low valley, which corresponds to a set of parameters with low loss. Each step uses only local information about the slope.
Gradient descent does not guarantee the absolute best solution, but in practice it finds very good ones for large models. Many variations exist that adjust step sizes automatically or add momentum, but they all share the same core idea of repeated small steps that reduce the error. It remains the workhorse of modern training.
The Learning Rate: Why Step Size Matters
The learning rate controls how large each step is. Google’s glossary describes it as a hyperparameter that tells gradient descent how strongly to adjust weights and biases. It is one of the most important settings in training, and getting it wrong can ruin the process. Small changes to it can have large effects.
If the learning rate is too large, updates overshoot, and training becomes unstable or fails to settle. If it is too small, training is painfully slow and may get stuck. Practitioners often start with a moderate rate and reduce it gradually as training progresses, taking big steps early and fine steps later.
The learning rate is an example of a hyperparameter, a setting chosen by people rather than learned by the model. Others include batch size and number of training rounds. Choosing them well is part of the craft of machine learning, and they are often tuned using a separate validation dataset. Tuning them is part science and part experience.
Batches, Iterations and Epochs
Modern training usually processes examples in groups called batches. Google’s glossary defines a batch as the set of examples used in one training iteration, and an iteration as a single update of the model’s parameters. Processing batches is far more efficient than updating after every single example. Batches also smooth out noise from individual examples.
For example, with 1,000 training examples and a batch size of 100, the model needs ten iterations to see the whole dataset once. One full pass through the training data is called an epoch. Training often runs for many epochs, so the model sees each example several times. Large models may train for only one or a few epochs because their datasets are so big.
More epochs are not always better. After a point, extra passes make the model fit the training data too closely, which leads to the problem of overfitting described next. Teams watch performance on validation data to decide when to stop training. Stopping at the right moment is a key skill. Validation scores guide the decision.
The Real Goal: Generalization, Not Memorization
The purpose of training is to perform well on new data the model has never seen, rather than on the training data itself. Google’s guide to datasets, generalization and overfitting describes generalization as the ability to perform well on previously unseen examples. Performance on unseen data is what counts.
Overfitting happens when a model learns the training data too precisely, including its noise and quirks, and then performs poorly on new data. It is like a student who memorizes past exam answers without understanding the subject, then struggles when the questions change slightly. It is one of the most common problems in machine learning.
Avoiding overfitting involves using enough varied data, keeping models appropriately sized for the task, applying regularization techniques that discourage overly complex patterns and stopping training at the right time. Our guide to preventing overfitting when fine-tuning covers practical methods. Prevention is easier than cure.
Training, Validation and Test Data
To check generalization, data is split into three sets. The training set is used to adjust parameters. The validation set is used during development to tune settings and decide when to stop training. The test set is held back until the end for an independent, final check of performance. Each set has a distinct job.
Google’s documentation recommends keeping these sets separate and warns against examples overlapping between them. The logic is simple: if the model has seen an example during training, testing on it measures memory, not generalization, and makes the model look better than it is. Strict separation keeps evaluation honest.
When you read claims about AI accuracy, ask how the test data was chosen and whether it reflects real use. A model tested on data very similar to its training data can show impressive numbers that do not hold up in practice, where inputs are messier and more varied. Real-world testing is the most reliable check.
Data Leakage Can Destroy an Evaluation
Data leakage happens when information that would not be available in real use sneaks into training or testing. A classic example is a medical model that learns from a hospital code added after diagnosis; it looks brilliant in testing because the code gives away the answer, then fails in real use. Leaks like this are surprisingly common.
Leakage can also happen when the same customer, document or event appears in both training and test sets, or when future information is used to predict the past. Each produces evaluation results that are too optimistic, sometimes dramatically so. Optimistic results can lead to costly launches. Check for it before you trust any score.
Preventing leakage requires careful thinking about what information is available at prediction time and strict separation of data by time, person or source when appropriate. It is one of the most common reasons AI projects disappoint after launch, and one of the easiest to miss. Careful review before launch prevents painful surprises.
Data Quality: What Beginners Underestimate
Good training data has four qualities. Is it accurate, with correct values and labels? Is it relevant to the task the model will perform? Is it representative of the people, places and situations the model will face? And is it current enough to reflect today’s conditions rather than an outdated past? Each question reveals a different kind of risk.
Missing any one of these causes problems. Inaccurate data teaches errors. Irrelevant data adds noise. Unrepresentative data produces a model that works for some groups and fails for others. Outdated data produces a model tuned to a world that no longer exists, which is especially risky in fast-changing areas.
Improving data quality is often the most effective way to improve a model, more so than switching algorithms. The Stanford finding about pruning, deduplication and curation reflects this at the frontier, and the same principle applies to small business projects with modest datasets. Clean, relevant data is the foundation of good AI.
AI Can Learn the Wrong Pattern
A model learns whatever patterns help it reduce loss, even if those patterns are accidental. A famous type of example is an image classifier that learns to recognize a background feature, such as snow, rather than the animal it was meant to identify, because the two appeared together in the training images.
These shortcut patterns can look like success in testing if the test data shares the same accident. They fail when the accident is absent. In business data, shortcuts might include a field that indirectly reveals the outcome or a proxy for a sensitive characteristic such as postcode standing in for ethnicity.
Guarding against wrong patterns means testing on varied data, checking which inputs drive predictions, reviewing errors carefully and involving people who understand the domain. It is a reminder that a model’s apparent intelligence comes entirely from the data it was given. Careful testing reveals what a model really learned.
The Four Major Learning Approaches
| Learning approach | Where the learning signal comes from | Simple example |
|---|---|---|
| Supervised learning | Human-provided or known labels | Spam vs not spam |
| Unsupervised learning | Structure within the data itself | Finding customer groups |
| Self-supervised learning | The data creates its own prediction tasks | Predicting the next word |
| Reinforcement learning | Rewards for actions | Learning to play a game |
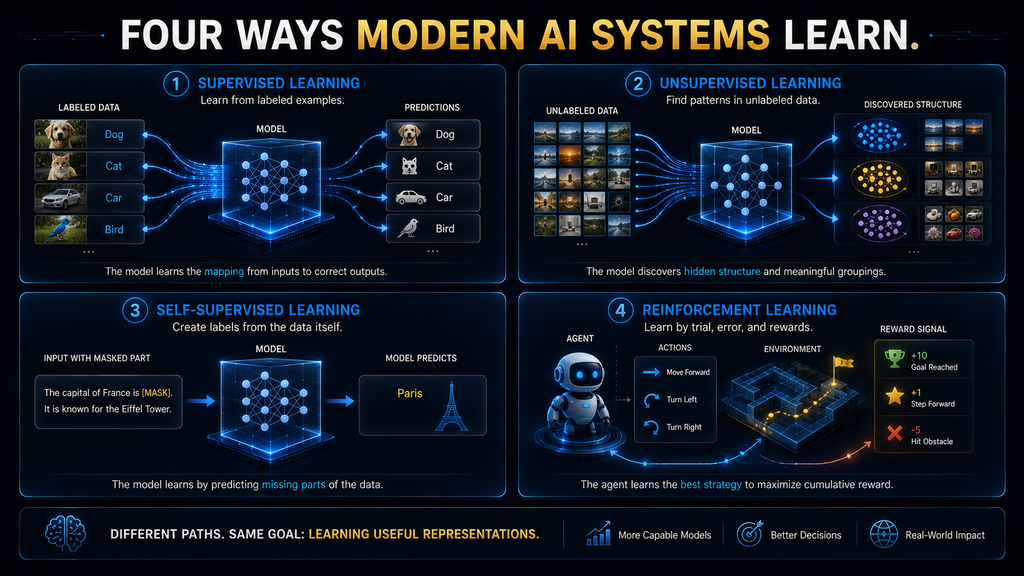
These approaches are often combined. Large language models, for example, use self-supervised learning during pretraining and supervised and reinforcement learning during post-training. Understanding each approach helps you understand what a model can and cannot be expected to do. The sections below explain each one briefly.
Supervised Learning
Supervised learning uses labeled examples, where the correct answer is known for each input. The model learns to map inputs to outputs, such as emails to spam labels or house features to prices. It is the most common approach in business, used for fraud detection, forecasting, classification and much more.
Unsupervised Learning
Unsupervised learning finds structure in data without labels. It groups similar customers, detects unusual transactions or compresses data into simpler forms. It is useful when labels are unavailable or when you want to discover patterns you did not know to look for, such as new customer segments. It often supports other learning methods too.
Self-Supervised Learning
Self-supervised learning creates its own learning task from the data. A language model hides the next word and learns to predict it, using the real next word as the answer. Because the data provides its own labels, this approach can learn from enormous unlabeled datasets, which is how foundation models are pretrained.
Reinforcement Learning
Reinforcement learning learns from rewards. An agent tries actions, receives feedback about how good the outcome was and adjusts to earn more reward over time. It powers game-playing AI and is used in post-training language models, where feedback on which answers are better acts as the reward. Designing good rewards is its hardest challenge.
How Large Language Models Learn
Large language models learn mainly through self-supervised next-token prediction. During pretraining, the model reads huge amounts of text and repeatedly predicts the next token, adjusting its parameters after each batch to reduce prediction errors. OpenAI’s help article describes this kind of learning of relationships in training data.
Through this process, the model captures grammar, facts, writing styles, coding patterns and common forms of reasoning, because predicting text well requires all of them. Our guide to AI tokens explains the units it predicts. All of this emerges from one simple prediction task. The scale of the data is what makes this possible.
What the model learns is a compressed statistical picture of its training data, not a database of stored documents. It can recall common facts well and generate new combinations of ideas, but it can also blend sources incorrectly or invent plausible details, which is why its output needs checking. Treat its output as a strong draft, not a final answer.
Pretraining and Post-Training Are Different
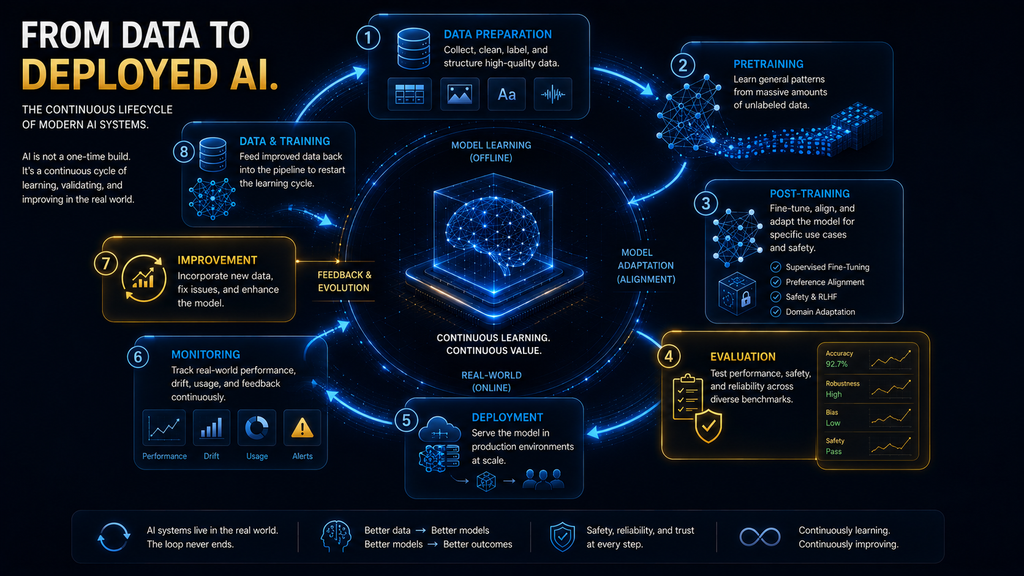
Pretraining is the broad, expensive first phase where a model learns general patterns from a huge dataset. The result is a base model with wide knowledge but no particular skill at following instructions or behaving like a helpful assistant. Pretraining can take weeks on large clusters of specialized chips.
Post-training refines that base model through techniques such as supervised fine-tuning on examples of good responses and reinforcement learning from feedback. It teaches the model to follow instructions, use a helpful tone, refuse harmful requests and perform well on target tasks. Much of an assistant’s usefulness comes from this phase.
After training comes evaluation, testing the model on many tasks and safety checks; deployment, releasing it in products; and ongoing improvement, where new data and feedback inform future versions. OpenAI’s help article describes its process in similar stages. Each stage feeds into the next. Improvement never really ends.
Fine-Tuning Is Not Training From Scratch
Fine-tuning continues training an existing model on a smaller, specialized dataset so it performs better on a particular task or style. It is far cheaper than pretraining a model from scratch, because the model already knows general patterns and only needs adjusting. It is a practical way to customize a model.
Businesses use fine-tuning to teach models their terminology, preferred formats or specialized tasks. Techniques such as LoRA, explained in our guide to LoRA, make fine-tuning even cheaper by adjusting only a small number of added parameters. Lower costs have made fine-tuning accessible to smaller teams.
Fine-tuning is not always the right tool. For adding knowledge, retrieval-augmented generation is often simpler and easier to update. Our guides to fine-tuning AI models and building a fine-tuning dataset explain when and how to fine-tune. Choosing the right method saves time and money. Start with the simplest option.
Does AI Learn From Every Conversation?
No, not in real time. When you chat with an assistant, the model’s parameters do not change. It uses your messages as context within that conversation, and some products store memories to reuse later, but the model itself is not retraining as you talk to it. Context and memory are product features, not live learning.
Whether your conversations are used to improve future models is a separate question that depends on the provider, the product and your settings. OpenAI’s help article describes model improvement as one possible use of user information, subject to the choices users make in their data controls. Policies differ between providers and account types.
If this matters to you, check your settings and your provider’s policies. Our guides to AI privacy risks and AI data retention explain what to look for and how to limit what you share. A few minutes of checking can make a real difference. Settings can change, so review them from time to time as products update.
Why AI Still Makes Mistakes After Training
Training never produces a perfect model. The training data can be incomplete, missing situations the model will later face. The data can contain errors, which the model learns as if they were true. The objective can be imperfect, rewarding behavior that does not match what people want. Each gap can lead to errors in use.
The model can overfit, performing well on familiar patterns and poorly on new ones. The world can change, making once-accurate patterns outdated. And evaluation can be incomplete, missing failure cases that only appear in real use. Each of these is a reason to keep checking AI output. No model is error-free.
For language models, a common visible failure is hallucination: confident but false statements. Our guide to AI hallucinations explains why it happens and how to reduce the risk in everyday use. Verification remains essential. Check important facts against a primary source, such as official documentation, before you rely on them.
The World Changes After the Model Learns
A model learns from a snapshot of the past. When conditions change, such as new customer behavior, new fraud tactics, new products or new regulations, the patterns it learned may no longer hold. This is often called data drift or distribution shift, and it slowly erodes performance. The decline is often gradual and easy to miss.
A fraud model trained before a new scam technique appears may miss it. A demand forecasting model trained before a major market change may produce poor forecasts. Our guides to AI inventory forecasting and AI fraud and anomaly detection discuss this risk. Change is the main enemy of an unmaintained model.
The fix is monitoring and retraining. Track model performance after deployment, compare recent inputs with training data and retrain or recalibrate when performance drops. A model is a system that needs maintenance as the world moves on. Plan and budget for maintenance from the start, because it pays off over the life of the model.
Why Monitoring Matters After Training
Monitoring checks that a deployed model keeps performing as expected. It tracks accuracy where outcomes can be measured, watches for changes in input data, flags unusual predictions and collects feedback from users and reviewers. Without monitoring, problems can grow quietly for months. Early warning saves expensive fixes later.
Good monitoring also looks at fairness and safety, not just overall accuracy. A model can keep the same average performance while getting worse for a specific group, which only shows up when results are broken down. Regular reviews by people who understand the domain catch issues that metrics miss. Numbers and people work best together.
For language models, monitoring includes reviewing samples of real conversations, tracking complaints and testing against known difficult cases. Our guide to human-in-the-loop AI explains how people and models can work together to keep quality high after launch. Feedback loops keep models useful over time.
A Simple End-to-End Example: An AI Spam Filter
Imagine building a spam filter. You collect 50,000 emails, each labeled spam or not spam by people. You clean the data, removing duplicates and fixing obvious labeling errors, then split it into training, validation and test sets so you can check generalization fairly. Clean, well-labeled data is the starting point.
Each email is converted into numbers representing its words, sender and links. The model predicts a spam probability for each training email, the loss measures how wrong it was, backpropagation finds which parameters to adjust and gradient descent updates them. After several epochs, predictions improve. Each pass refines the model a little more.
You use the validation set to choose settings and decide when to stop, then check the test set once for an honest final score. After launch, you monitor performance. When spammers change tactics, accuracy drops, so you collect new labeled examples and retrain. That cycle is how real AI systems stay useful.
Why Rule-Based Systems Still Exist
Not every problem needs machine learning. Rules are predictable, easy to explain and cheap to run. If a task follows clear, stable logic, such as calculating tax or routing a form by type, hand-written rules are often the better choice and easier to audit. Simple problems deserve simple solutions. Start with rules where they work.
Machine learning makes sense when rules are hard to write because the patterns are complex, subtle or constantly changing, such as spotting spam, recognizing images or understanding language. Many real systems combine both, using rules for clear-cut cases and models for the rest. The combination often works best.
The trade-off is flexibility versus predictability. Learned models handle messy, varied input but can behave unexpectedly. Rules behave exactly as written but break when reality does not match their assumptions. Choosing the right mix is a design decision, not a technology preference. Pick the tool that fits the problem.
Why AI Can Learn Bias
If historical data reflects unfair decisions or unequal treatment, a model trained on it can reproduce those patterns. A hiring model trained on past hiring decisions may learn to favor the groups that were favored before, even if no one intended it and protected characteristics were removed from the data.
Bias can also come from unrepresentative data, where some groups appear rarely, and from proxies, where innocent-looking features correlate with sensitive ones. The model has no intent to be unfair; it simply finds patterns that reduce loss, and unfair patterns can do that just as well as fair ones. That is why fairness has to be checked deliberately.
Detecting and reducing bias requires testing outcomes across groups, reviewing which features influence predictions and adjusting data or objectives when problems appear. Our guide to detecting and reducing AI bias explains practical steps. Fairness needs ongoing attention, not a single check. Document what you test.
The Objective Can Matter More Than the Model
Google’s glossary defines an objective as the metric an algorithm is trying to optimize. That choice is powerful. A recommendation system optimized only for clicks may learn to promote sensational content. A support model optimized only for short conversations may end chats before problems are solved. The objective shapes behavior in ways that are easy to overlook.
That is why responsible machine learning starts with a different question. Instead of “which model should we use?”, ask “what exactly are we asking the system to optimize, and what side effects might that create?” A well-chosen objective often matters more than a more sophisticated algorithm. Good goals lead to good systems.
Our guide to AI product recommendations shows how objective choices shape what customers see. The same lesson applies across fields: define success carefully, measure what matters and watch for unintended effects. Measuring the right thing is half the battle. Good objectives serve customers and the business together.
Why Synthetic Data Is Becoming Important
Synthetic data is data generated by algorithms or AI models rather than collected from the real world. OpenAI’s help article says it increasingly uses synthetic data in some training processes, such as generating synthetic prompts and multilingual examples. Its use is growing across the industry. It is a tool with clear limits.
Synthetic data can fill gaps, create examples of rare situations and protect privacy by avoiding real personal data. But it is not a magic replacement. Stanford’s 2026 AI Index reports that synthetic data is still not replacing real data in pretraining, even as data quality and post-training techniques show promise.
Synthetic data can also carry forward the flaws of the model that generated it. Used carefully, mixed with real data and checked for quality, it is a useful tool. Used carelessly, it can amplify errors or narrow a model’s view of the world. Quality checks are essential. Real data still anchors good models.
Frontier AI Training Is Becoming Less Transparent
Stanford’s 2026 AI Index notes that the most capable models are now the least transparent, with details such as training code, parameter counts, dataset sizes and training duration no longer disclosed for several leading models. The same chapter reports that industry produced over 90% of notable AI models in 2025.
That lack of transparency makes it harder for users and researchers to judge how a model was trained, what data it learned from and what risks it may carry. Be cautious with confident claims about what a particular model was or was not trained on, unless the company has documented it. Healthy skepticism is warranted.
For practical decisions, focus on what you can test: how the model performs on your tasks, how it handles your data and what controls the provider offers. Independent evaluations and your own testing are more reliable guides than marketing descriptions of training. Testing on your own tasks is the best guide.
Common Myths About How AI Learns
Myth: AI Learns Exactly Like Humans
AI adjusts numerical parameters to reduce errors on examples. People build understanding through experience, reasoning and context. The comparison is useful as a loose metaphor but misleading in detail, especially about what models understand. Keep the differences in mind. Models do not experience or understand the world the way you do.
Myth: More Data Always Creates Better AI
More data helps only when it adds accurate, relevant and varied examples. Narrow or noisy data can make models worse. Stanford’s findings on curation show that better data can beat more data, even at the frontier. Quality beats quantity. Curation is a competitive advantage, and it is often cheaper than collecting more data.
Myth: AI Simply Memorizes Its Training Data
Models learn patterns spread across parameters rather than storing copies of training examples, though some memorization of specific content can occur. That is why they can generate new combinations of ideas, and also why they can blend sources incorrectly. Checking facts remains important. Verify what matters.
Myth: Every Conversation Retrains the AI
Parameters do not change during your chat. Some products store memories, and conversations may be used for future training depending on settings, but the model is not learning from you in real time. Check your settings if this matters to you. Memory features are separate from model training and can usually be managed in settings.
Myth: A Bigger Model Always Learns Better
Size helps, but data quality, objectives and post-training matter as much. Stanford reports a much smaller model achieving results comparable to a far larger one on several benchmarks through careful curation. Smaller models can be excellent choices, so test candidates on your own task and budget before deciding.
A Practical Checklist for Judging AI Claims
When a vendor says its AI “learns from your data,” ask what data it uses, how that data is labeled and checked, and whether it covers your situations. Ask how the model was tested, on what data, and whether that test data was kept separate from training data. Honest, specific answers reveal a lot about a product.
Ask what the model is optimized for and how success is measured in production. Ask how often it is monitored and retrained, how bias is checked and what happens to your data. Clear answers to these questions suggest a mature product; vague answers suggest risk. Ask before you buy, and get the answers in writing.
These questions apply whether you are buying a fraud tool, a recommendation engine or an AI assistant. Our guide to building an AI risk management framework turns them into a repeatable review process for businesses. A consistent review process saves time and makes vendor comparisons fairer each time you use it.
How We Researched This Guide
This guide is based on published documentation and research, not on training models for this article. We reviewed OpenAI’s help article on how ChatGPT and its foundation models are developed, the research and development chapter of Stanford’s 2026 AI Index, Google’s Machine Learning Crash Course and machine learning glossary, and the Deep Learning textbook by Goodfellow, Bengio and Courville.
The AI learning loop, the four data-quality questions and the checklist are AI Hustle World’s editorial frameworks, built on those sources. Examples such as the spam filter and fraud datasets are illustrations, not case studies. The field moves fast, so check current documentation for specific products. We update this guide as the field evolves.
Final Thoughts
AI learns by making predictions, measuring errors and adjusting parameters, over and over, until its outputs fit the patterns in its training data. That simple loop, scaled up with enormous datasets and computing power, produces systems that can recognize images, detect fraud and hold conversations. The loop is simple; the scale is what makes it powerful.
What a model learns depends on the data, the representation, the objective and the evaluation built around it. Good data, a well-chosen objective and honest testing produce useful models. Narrow data, the wrong objective or leaked test data produce models that look good on paper and fail in practice. The details make all the difference.
Remember that AI does not learn what you want just because you give it more information. It learns what its data and objective reward. Ask good questions about both, monitor models after launch and keep people involved where mistakes matter. To see how these ideas apply to language models, read our guide to what a large language model is.
Choose the AI Tool That Solves the Right Problem
Training data is turned into tokens, so learn what tokens are and why they shape cost and limits.
Learn What AI Tokens Are →Frequently Asked Questions
How does AI learn from data in simple terms?
It makes predictions on examples, measures how wrong they are and adjusts its internal numbers to do slightly better. Repeated many times, this captures patterns it can apply to new examples.
What are parameters in AI?
Parameters are the adjustable numbers inside a model, also called weights. Training tunes them, and together they store the patterns the model has learned from data.
What is a loss function?
A loss function measures how far a model’s prediction is from the correct answer. Training tries to reduce the loss, so the choice of loss defines what “better” means.
What is overfitting?
Overfitting is when a model learns its training data too closely, including noise, and performs poorly on new data. Good data, the right model size and early stopping help prevent it.
What is the difference between supervised and unsupervised learning?
Supervised learning uses labeled examples with known answers. Unsupervised learning finds structure in unlabeled data, such as grouping similar customers.
How do large language models learn?
Mainly by self-supervised next-token prediction on huge text datasets, followed by post-training with examples and feedback that teach them to follow instructions.
Does ChatGPT learn from my conversations?
Not in real time; the model does not change during your chat. Whether conversations help train future models depends on the provider’s policy and your data settings.
Why can AI be biased?
Models learn patterns in their training data, including unfair historical patterns and proxies for sensitive traits. Testing outcomes across groups helps find and reduce bias.
Is more training data always better?
No. Data must be accurate, relevant, representative and current. Stanford’s 2026 AI Index highlights cases where better curation beat sheer size.
Can synthetic data replace real data?
Not fully. Stanford’s 2026 AI Index reports synthetic data is not replacing real data in pretraining, though it can help in narrower uses and fill gaps.
Related Guides
- What Is a Large Language Model (LLM)? How LLMs Really Work
- How to Prepare a Dataset for Fine-Tuning a Language Model
- How to Evaluate RAG Retrieval Quality: Metrics, Testing & Failure Analysis
Written by
Muntasir Ahmad Chowdhury
Founder, AI Hustle World
Muntasir Ahmad Chowdhury is the Founder of AI Hustle World, an independent publication dedicated to making Artificial Intelligence practical, trustworthy, and easy to understand. He researches AI tools, automation, customer service, productivity, and real-world business applications, helping readers make smarter technology decisions through research-driven, experience-backed content.
Expertise:
AI Tools • AI Automation • AI Customer Service • AI Productivity • Generative AI • AI Workflows
Get Smarter With AI
Enjoyed this guide? Get practical AI tools, tutorials, and honest reviews delivered to your inbox.