Evidence: Documentation reviewed
Last checked: October 2026
What was done: Written from official documentation and the published sources linked in this article. Not hands-on tested.
Files: None
Affiliate links: No
Last updated: October 2026
Understanding AI Hallucinations: Why AI Gives Wrong Answers
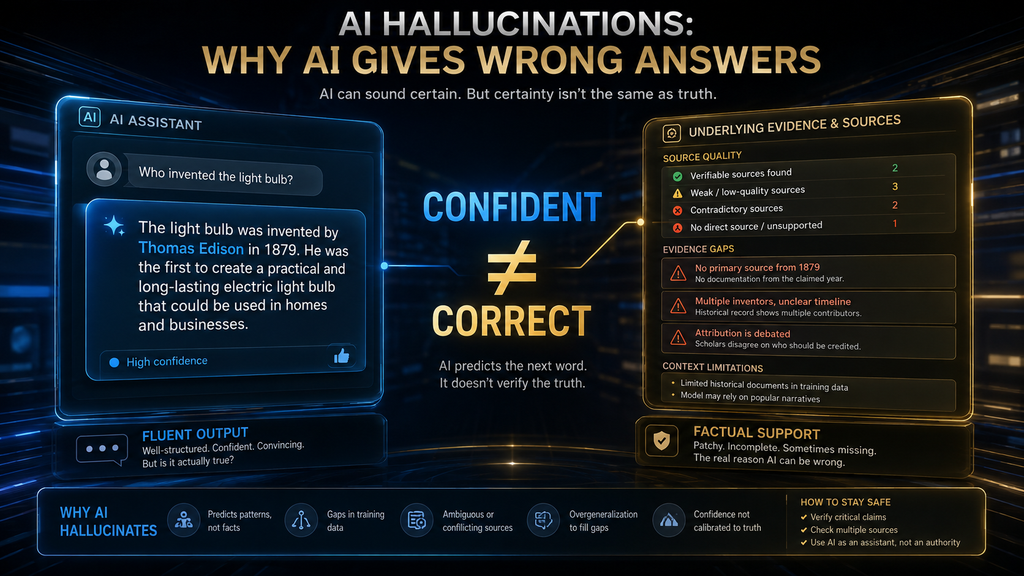
An AI hallucination is an answer that sounds plausible and confident but is false, unsupported or invented. AI gives wrong answers of this kind because language models generate likely text rather than look up verified facts, and because they are often rewarded for answering instead of admitting uncertainty.
AI can write a convincing explanation of a topic you barely understand. That is one of its strengths, and it is also one of its biggest risks, because you are least able to spot an error in exactly the areas where you most need help.
Search engines and databases can return wrong information too. What makes hallucination different is the delivery: the false statement arrives in fluent, well-organized prose with no visible sign that anything is wrong.
OpenAI’s research on why language models hallucinate defines hallucinations as plausible but false statements generated by language models. It adds that they remain a fundamental challenge for all large language models, including the newest ones.
That matters more each year, as AI moves into customer support, research, coding, healthcare and business decisions. A wrong answer in a brainstorm costs nothing, while the same wrong answer in a contract or a patient summary can be expensive.
This guide explains why hallucinations happen, how to recognize the main types and when they are most likely. You will also get the AI Hallucination Risk Ladder, the AI Reliability Stack, a five-minute verification routine and prompts that reduce the risk.
What an AI Hallucination Is
An AI hallucination is an output that contains information that is false, fabricated or inconsistent with the available evidence, while being presented as a normal answer. The model does not flag it, hedge it or mark it as a guess.
Hallucinations take many forms. A model may invent a statistic, attribute a quote to someone who never said it, describe a feature a product does not have or cite a study that does not exist.
Researchers have studied the problem for years. An influential survey of hallucination in natural language generation documented it across summarization, translation, dialogue and question answering well before today’s chat assistants became popular.
Standards bodies treat it as a recognized risk as well. Guidance built on the NIST AI Risk Management Framework uses the term confabulation for the same behavior, and lists it among the risks organizations should manage when they deploy generative AI.
Hallucinations, Errors and Outdated Answers Are Different Problems
Not every wrong AI answer is a hallucination, and the difference matters because the fixes differ. A simple error is a mistake in a task the model can normally do, such as a slip in arithmetic.
An outdated answer was true when the model was trained and is no longer true. A price, a law or a product feature may have changed since, and the model has no way of knowing unless it can search.
A hallucination is an invented detail presented as fact. If you ask for sources and the AI gives you a convincing paper title, author list and DOI for a paper that does not exist, that is the classic pattern.
Each problem has its own remedy. Errors are reduced by checking the work, outdated answers by using current sources, and hallucinations by grounding the model in evidence and letting it say when it does not know.
Why AI Hallucinates: Prediction Is Not Knowledge
Language models learn by predicting the next word across enormous amounts of text. That training teaches them the patterns of language extremely well, and our explainer on what a large language model is covers the mechanics.
Patterns that repeat often are learned reliably. Grammar, spelling, common phrases and widely repeated facts appear so frequently that the model reproduces them with great accuracy.
Rare facts are a different matter. A 2026 paper in Nature, Evaluating large language models for accuracy incentivizes hallucinations, shows that facts lacking repeated support in training data, such as one-off details, yield unavoidable errors, while recurring regularities such as grammar do not.
That is why a model can write a flawless paragraph about a person and still get their birthday wrong. The sentence structure is a strong pattern, and the specific date is a single detail that may have appeared only a handful of times.
The core point is simple. Language models are very good at generating probable text, and probable is not the same as true.
The Incentive Problem: AI Is Rewarded for Guessing
The second cause is less obvious and may matter more. Models are tested and tuned using evaluations, and most evaluations reward a correct answer while giving nothing for “I do not know.”
Think about a student facing a multiple-choice exam with no penalty for wrong answers. Guessing is the rational strategy, because a blank scores zero and a guess sometimes scores a point.
The Nature paper argues that models face the same incentive. It shows how next-word prediction and accuracy-based evaluations inadvertently reward unwarranted guessing, so a model that guesses can look better on a leaderboard than one that abstains honestly.
OpenAI gives a concrete example using one of its own evaluations. On the SimpleQA test, an older model answered almost everything, while a newer model declined to answer about half the questions.
| Metric | Newer model (gpt-5-thinking-mini) | Older model (o4-mini) |
|---|---|---|
| Abstention rate (no specific answer given) | 52% | 1% |
| Accuracy rate (right answer) | 22% | 24% |
| Error rate (wrong answer) | 26% | 75% |
The older model scored slightly higher on accuracy and produced almost three times as many wrong answers. If you judged only by accuracy, you would pick the model that hallucinates far more often.
The lesson reaches beyond these two models. Declining to answer is a feature of reliability, and any system that punishes it will tend to produce confident guesses.
For everyday users, the practical meaning is simple. When you compare AI tools, a tool that sometimes says it cannot verify an answer may be the more trustworthy one, even though it feels less impressive than a tool that always responds with certainty.
Why AI Sounds Confident When It Is Wrong
People judge reliability by fluency, detail, structure and tone. A human expert who speaks clearly and gives specifics usually knows the subject.
AI can produce all four signals without having evidence for the claim. Fluency comes from language patterns, and it says nothing about whether a particular fact is supported.
Compare two responses to a question about a research paper. The first says, “I am not certain when that paper was published and could not verify the journal.”
The second says, “The paper was published on March 14, 1998, in the International Journal of Computational Systems, Volume 7, Issue 2.” The second feels more trustworthy because it is specific, and it may be entirely invented.
This is the trap. Specific detail raises our confidence, while in AI output it is often the specific details, such as dates, numbers, names and citations, that are most likely to be wrong.
Seven Types of Hallucination You Should Recognize
A general warning that “AI is sometimes wrong” is not enough to protect you. Knowing the common types makes them much easier to spot.
| Type | What it looks like | Example |
|---|---|---|
| Factual | A false statement inside an otherwise accurate answer | A company “founded in 2001” that was founded in 2004 |
| Citation | A reference that does not exist or does not say what is claimed | A convincing paper title with a fake DOI |
| Entity | An invented person, product, law or organization | A regulation with an official-sounding name that was never passed |
| Numerical | A wrong figure, percentage or calculation | A market size that appears in no source |
| Temporal | Outdated or misdated information presented as current | A discontinued pricing plan described as available |
| Source-grounding | A supplied document is misrepresented | “The report recommends X” when it only mentions X |
| Instruction | The right knowledge, applied to the wrong task | Summarizing the wrong section, or ignoring a stated constraint |
Citation hallucinations are especially dangerous in research and academic work. A reference can look so convincing that a reader never thinks to check it.
Source-grounding failures are the easiest to miss in business settings. The AI was given the right document, so people assume the summary is faithful, and nobody compares it with the original.
A Real Case: Fabricated Citations in Court
The best-known example comes from a United States federal court in 2023. In Mata v. Avianca, lawyers filed a brief that cited several earlier court decisions in support of their client.
The decisions did not exist. They had been produced by a chatbot used for legal research, complete with plausible case names, courts and quotations, and nobody on the team had checked them against a legal database.
The judge sanctioned the lawyers and their firm and ordered them to pay a fine. The case became a standard warning in legal training about relying on AI output without verification.
The lesson applies well beyond law. The chatbot did exactly what it was built to do, which is to produce a plausible answer, and the failure was a workflow in which nobody verified the citations before they reached a judge.
Where Hallucinations Are Most Likely
Hallucination risk is not evenly spread. It rises sharply in a handful of predictable situations, and learning them tells you when to slow down.
Rare information is the first. The less often a fact appears in public text, the weaker the model’s pattern for it, which is why obscure people, small companies and niche topics produce more invented details.
Missing and current information come next. If the answer is not in the model’s training data, or changed after training ended, the model may fill the gap with something that sounds right.
Ambiguous questions and hidden assumptions add to the risk. A question that assumes something false, such as “Why did the company cancel the product?” when it did not, invites the model to explain an event that never happened.
High specificity is the last warning sign. Requests for exact numbers, dates, quotations, page references and URLs push the model toward precise-looking output that it often cannot support.
The Hallucination Risk Ladder
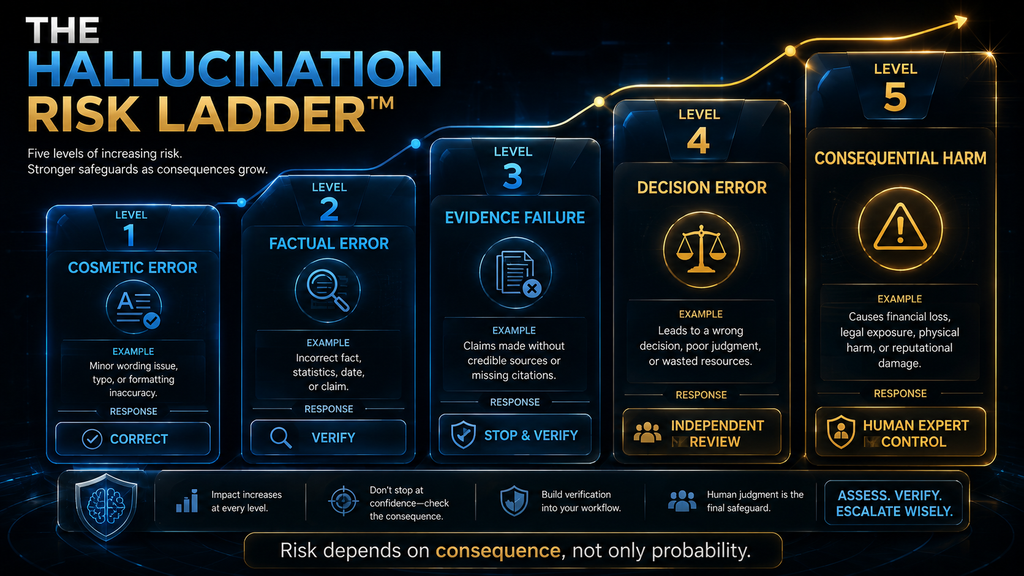
The right response to a possible hallucination depends on what happens if it is wrong. The AI Hustle World Hallucination Risk Ladder sorts errors into five levels by consequence.
| Level | What it is | Example | Response |
|---|---|---|---|
| 1. Cosmetic error | Minor mistake with little consequence | A typo in a low-stakes draft | Correct and continue |
| 2. Factual error | Incorrect information that affects understanding | A wrong publication date | Verify before publishing |
| 3. Evidence failure | Fabricated citation or misread source | A research article that does not exist | Stop and verify the evidence |
| 4. Decision error | Wrong information that could affect a business, financial or academic decision | An incorrect figure in a board report | Independent verification is mandatory |
| 5. Consequential harm | Errors affecting health, safety, legal rights or money | An incorrect medication instruction | AI is never the final authority |
The ladder replaces a vague sense of caution with a practical rule. A 5% chance of a wrong film release date is trivial, while a 5% chance of a wrong medication instruction is unacceptable.
Use it to set your effort. Levels one and two need a quick check, level three needs the source in front of you, and levels four and five need a qualified person.
Why Bigger and Newer Models Still Hallucinate
It is tempting to assume that the next model will solve the problem. The evidence does not support that simple conclusion.
Newer models often hallucinate less on standard tests, and that progress is real. OpenAI still states that hallucinations remain a challenge even as models become more capable.
The reason is partly logical. A more capable model does not gain access to information that is missing from its evidence, so some questions have no reliable answer available to it.
For those questions, the right behavior is to say so. That is a matter of training incentives and product design, which is why the Nature paper frames part of the problem as one of evaluation rather than raw capability.
Research on measurement continues as well. Benchmarks such as FactBench, a dynamic test of language model factuality on real-world prompts, exist because the field still needs better ways to measure how often models state things that are not true.
The AI Reliability Stack
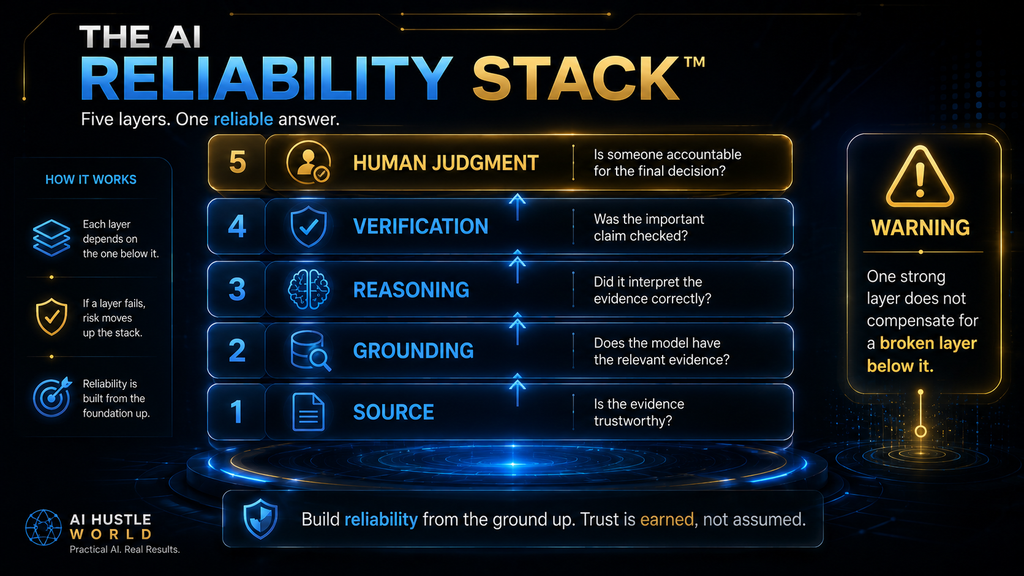
Reliable AI output depends on several layers working together. The AI Hustle World AI Reliability Stack names five of them, and each solves a different problem.
| Layer | Question it answers | What can go wrong |
|---|---|---|
| 1. Source | Is the underlying information trustworthy? | The source itself is wrong or outdated |
| 2. Grounding | Was the answer based on that source? | The model answered from memory instead |
| 3. Reasoning | Did the model interpret the evidence correctly? | A correct document is misread |
| 4. Verification | Was the important claim independently checked? | Nobody compared the answer with the source |
| 5. Human judgment | Did an accountable person review the decision? | The output went straight into action |
Each layer covers a gap the others leave open. Better sources do not guarantee correct reasoning, better reasoning does not guarantee current information, and a grounded answer is not automatically a verified one.
You do not need every layer for every task. A brainstorm needs none of them, while a customer-facing answer about refunds should have all five.
Does RAG Eliminate Hallucinations?
No. Retrieval-augmented generation, or RAG, reduces hallucination risk by giving the model relevant evidence at the moment it answers, instead of forcing it to rely on memory.
The technique was introduced in the paper on retrieval-augmented generation for knowledge-intensive tasks, and our complete guide to RAG explains how it works. It is now the standard way to connect a model to company documents.
The evidence for RAG is encouraging and limited. A 2026 systematic review of hallucination mitigation in healthcare AI screened 427 studies, included 44, and found RAG to be the most frequently evaluated strategy.
In that review, RAG approaches showed reductions in hallucinations of 30% to 50%. That is a meaningful improvement and a long way from elimination.
RAG helps when the answer exists in the retrieved documents. It does not fix retrieval of the wrong passage, conflicting sources, outdated documents or a model that misreads what it retrieved, as our guide on reducing hallucinations with RAG explains.
The quality of the documents matters as much as the retrieval. A system that retrieves an outdated policy or a draft that was never approved will produce a well-grounded answer that is still wrong, so the source library needs an owner and regular cleaning.
How Search and Tools Change the Picture
Many assistants can now search the web, run code and call other tools. Each of these reduces a specific kind of hallucination.
Web search helps with current information, because the model can read a recent page instead of relying on training data. A calculator or code tool helps with arithmetic, because the model computes the answer instead of predicting it.
Tools introduce their own risks. A search result can be wrong, an AI can misread a page, and a summary of five sources can blend them into a claim none of them made.
The practical rule is to treat tool use as better grounding, not as verification. Our explainer on how AI agents use tools shows what happens behind the scenes, and the links an assistant provides still need opening.
Questions That Invite Hallucination, and Better Versions
The way a question is asked changes the risk. Some phrasings almost guarantee an invented answer, because they demand specifics the model may not have or assume something that is not true.
| Risky question | Why it invites a hallucination | Safer version |
|---|---|---|
| “Give me five studies proving that X works.” | Demands a fixed number of sources and assumes the conclusion | “What does the research say about X? Link the sources so I can check them.” |
| “Why did the company cancel this product?” | Assumes an event that may not have happened | “Did the company cancel this product? Cite where that is reported.” |
| “What was their exact revenue in 2019?” | Asks for a precise figure the model may not know | “What revenue was reported for 2019, by which source and when?” |
| “Quote what the author said about this.” | Requests a verbatim quotation from memory | “Summarize the author’s view and tell me where I can read the original.” |
| “You must give me an answer.” | Removes the option to express uncertainty | “If you are not sure, say so and tell me what would settle it.” |
The pattern in the safer versions is consistent. They leave room for “I do not know,” they ask for sources you can open, and they avoid building a conclusion into the question.
How Leading Questions and Forced Answers Raise the Risk
Models tend to go along with the framing they are given. If your question assumes a claim is true, the model is more likely to elaborate on it than to challenge it.
Pressure works the same way. Instructions such as “be confident,” “do not hedge” or “always give a definite answer” remove the model’s safest response, which is to report that the evidence is thin.
Long conversations add a further risk. Over many turns, an early guess can be repeated until it reads like an established fact, and both you and the model stop questioning it.
The remedy is to ask neutral questions, allow uncertainty and restate the facts you have confirmed from time to time. For important work, start a fresh conversation with only the verified information.
How to Reduce Hallucination Risk as a User
You cannot remove hallucinations, but you can make them much less likely. Six habits do most of the work.
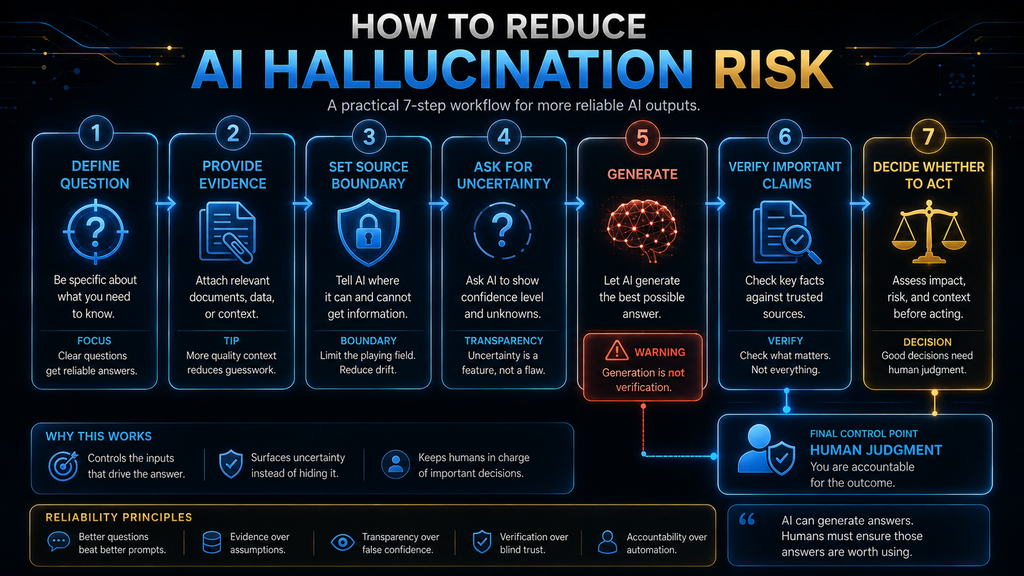
Give the AI the relevant source. If you are asking about a specific document, provide it, because a model reading the text is far more reliable than a model recalling it.
Define the evidence boundary. Say “use only the information in the supplied document, and if the answer is not there, say it is not available,” which removes the pressure to fill gaps.
Ask for uncertainty and separate facts from inference. Instructions such as “tell me which parts you are unsure about” and “label anything that is your interpretation” make weak claims easier to see.
Ask for sources, and remember that a citation is a starting point, not proof. Finally, break complex tasks into steps, so you can check each stage before the next one builds on it.
Our guides to writing prompts for accurate answers and asking AI better questions cover these techniques in depth.
A Practical Hallucination-Reduction Prompt
For any question where accuracy matters, a reusable prompt saves time. The version below combines the habits from the previous section.
“Answer the following question using only the supplied information and clearly identified authoritative sources. Separate verified facts from inference. If the evidence is insufficient or conflicting, say so instead of guessing. For every important factual claim, give the supporting source or state what still needs verification.”
For high-stakes questions, add one more line: “Explain what I should independently verify before acting on this answer.” That turns the AI into a guide for your own checking.
No prompt makes a model reliable on its own. What a good prompt does is change the model’s fallback, from producing a confident guess to reporting a gap, and that is a real improvement.
How to Check an AI Answer in Five Minutes
Verification does not need to be slow. A short routine catches most serious problems before they travel.
First, identify the claims that matter. In most answers only three or four statements would cause harm if they were wrong, and those are the ones to check.
Second, open the sources. If the AI cited something, confirm that the source exists and that it says what the answer claims, and if it cited nothing, search for the claim yourself.
Third, check numbers, dates and names against an authoritative source. Fourth, ask whether the answer could be out of date, particularly for prices, laws and product features.
Fifth, for anything consequential, ask a second source, whether another tool or a person who knows the subject. Our framework for checking AI information expands each of these steps.
Citation Checks: Confidence Is Not Accuracy
Citations deserve their own routine, because a fabricated reference looks exactly like a real one. Authors, journal, year and page numbers can all be plausible and all be wrong.
The check has four parts. Open the source, confirm the title and authors, confirm where and when it was published, and confirm that the claim appears in the source.
The last step is the one people skip. A real paper cited for something it does not say is still a hallucination, and it is harder to catch than a paper that does not exist.
If you publish or submit work, check every citation the AI produced, without exception. The time is small compared with the cost of a fabricated reference found by a reviewer, a client or a judge.
How Developers Reduce Hallucination Risk
The problem becomes more complex when AI runs inside software or business processes. Developers combine several controls, because no single one is enough.
Retrieval grounds answers in approved documents, and tool use lets the model look things up or calculate instead of guessing. Structured outputs constrain the format, as our guide to structured prompts explains.
Evaluation measures how often the system is wrong before and after each change. Our guide to evaluating RAG retrieval quality covers the methods, and human review catches the cases automated checks miss.
Red teaming and monitoring complete the set. The healthcare review found human-in-the-loop strategies achieved reductions of up to 95% while raising scalability concerns, and that red teaming uncovered vulnerabilities other methods missed.
Hallucinations in Healthcare: Why Stakes Change the Rules
Healthcare shows clearly how consequence changes the standard. The same error rate that is tolerable in a marketing draft is unacceptable in a clinical setting.
The BMC Health Services Research review describes the failures seen in clinical use. They include fabricated citations, incorrect treatment statements and inaccurate summaries of patient context, each of which can lead to unsafe decisions.
The review identified seven groups of mitigation strategies: RAG, knowledge graphs, self-reflection, specialized evaluation metrics, human-in-the-loop approaches, specialized training and red teaming. No single strategy was sufficient.
The general principle carries to every field. The higher the cost of an error, the stronger the verification and human oversight need to be, as our guide to human-in-the-loop AI explains.
Hallucinations in Code, Legal and Financial Work
Each professional field has its own typical hallucination. In software, the classic case is an invented function, library or parameter that looks correct and does not exist.
Code has one advantage, which is that it can be run. Our guide on preventing hallucinated APIs in AI-generated code shows how tests and documentation checks catch these errors early.
In legal work, the typical failure is the fabricated or misdescribed authority, as the court case above shows. Our guide to AI legal research explains how lawyers use AI without handing over legal judgment.
In finance, the risk is the plausible number. A growth rate, a ratio or a forecast that appears in no source can pass through a spreadsheet and into a decision, so every figure needs a traceable origin.
Hallucinations in Customer Support and Chatbots
Customer-facing chatbots raise the stakes, because the customer treats the answer as the company’s word. A bot that invents a refund rule or a delivery promise creates a commitment the business never made.
The usual cause is a bot answering from general knowledge when it should answer from the company’s own policies. Grounding it in an approved knowledge base, and instructing it to hand over when the answer is not there, removes most of the risk.
Escalation is the safety net. A support assistant should recognize questions about money, legal rights, safety and complaints, and route them to a person instead of composing a plausible reply.
Our explainer on AI customer service covers how these systems are built. The principle is the same as everywhere else: the bot should answer what it can support and pass on what it cannot.
Hallucinations in Summaries and Meeting Notes
Summaries feel safe because the source material was provided. They still go wrong in three recognizable ways.
The first is the invented detail, such as an action item nobody agreed or a deadline nobody stated. The second is the wrong attribution, where a comment is assigned to the wrong person.
The third is the dropped condition. “We will ship in March if testing passes” becomes “we will ship in March,” which changes the meaning and can cause real trouble later.
Check summaries against the source for decisions, names, numbers and dates. Those are the items people act on, and they take only a minute or two to confirm.
AI Hallucination Risk by Task
Risk varies more by task than by tool. The table gives a starting point for how much checking each kind of work needs.
| Task | Typical risk | Recommended control |
|---|---|---|
| Brainstorming | Low | Human selection |
| Rewriting | Low to medium | Review that the meaning is unchanged |
| Summarization | Medium | Compare against the source |
| General research | Medium | Source verification |
| Current facts | Medium to high | Search plus a source check |
| Citation generation | High | Verify every citation |
| Financial analysis | High | Independent evidence |
| Medical guidance | High | Qualified professional and authoritative sources |
| Legal interpretation | High | Qualified professional and primary sources |
| Security decisions | High | Expert verification and testing |
Notice that the risky tasks share a feature. They depend on specific facts that must be right, while the low-risk tasks depend on ideas and wording, where a wrong detail does little harm.
When to Trust an AI Answer: Green, Yellow and Red
A simple traffic-light rule makes daily decisions easier. It sorts answers by the consequence of being wrong.
Green covers low-consequence uses such as brainstorming, rewording, outlining and casual explanation. Use the output freely, with a quick read for sense.
Yellow covers moderate-consequence uses such as published content, customer messages, reports and study material. Check the facts that matter before anything leaves your hands.
Red covers high-consequence uses such as medical, legal, financial and safety decisions. Use authoritative evidence and qualified people, and treat the AI answer as preparation for that conversation.
The goal is appropriate verification for the stakes. Checking everything to the same standard wastes time, and checking nothing eventually costs far more.
The Cost of an Unchecked Hallucination
The cost of a hallucination depends on how far it travels before someone notices. An error caught in a draft costs a minute, and the same error in a published report costs credibility.
Automation makes the travel faster. An AI answer can flow into an automated report, then a management decision, then a customer action, and the original mistake may sit several steps behind the visible problem.
That is why the average error rate is a poor guide. One fake citation in a hundred pages is a small rate and can still end a contract or damage a reputation.
The economics favor early checks. Five minutes of verification at the point of creation is almost always cheaper than tracing and correcting an error after it has spread through documents and systems.
Common Myths About Hallucinations
Several beliefs about hallucinations are widespread and wrong. Correcting them makes your use of AI safer.
- “Only old models hallucinate.” Newer models do it less often, and it remains a challenge for the most advanced systems.
- “A detailed answer is probably accurate.” Detail is a product of fluency, and specific details are often where errors hide.
- “If there are citations, it is verified.” Citations can be invented or misapplied, so they need opening.
- “RAG eliminates hallucinations.” It improves grounding and leaves retrieval and interpretation errors.
- “Just tell the AI not to hallucinate.” That instruction alone does little; evidence and verification do more.
- “Bigger models will solve it.” Some questions have no reliable answer, and a good system must know when to abstain.
The common thread is that reliability comes from the whole workflow. A better model helps, and it does not replace evidence, checking and judgment.
A Reliability Checklist You Can Reuse
Before you rely on an important AI answer, run through seven quick questions. They take a minute and cover the main failure points.
- Evidence: what is this answer based on?
- Recency: could the information have changed?
- Specificity: are there exact numbers, dates or names that need checking?
- Consistency: does the answer contradict itself or what I already know?
- Citation: do the sources exist and say this?
- Uncertainty: did the AI express any doubt, and where?
- Consequence: what happens if this is wrong?
The last question decides how much effort the others deserve. If the consequence is small, a quick read is enough, and if it is large, every earlier question needs a real answer.
What to Do When You Find a Hallucination
Finding an error is useful information, and how you respond matters. Start by correcting it at the source, in the document or message where it appeared.
Then trace where it travelled. If the wrong figure was copied into a report, a slide or an email, each copy needs fixing, and anyone who relied on it should be told.
Next, ask why it happened. The usual causes are a question that demanded specifics, missing source material or a summary nobody compared with the original, and each has a simple fix.
Finally, record it. A short list of the hallucinations your team has caught is the best training material you can have, because it shows exactly where your own workflow is exposed.
Teaching a Team to Spot Hallucinations
Individual care is not enough once several people use AI. A team needs shared habits, or quality depends on who happened to do the work.
Show real examples. People learn far faster from an invented citation or a wrong figure that nearly went out than from a general warning about accuracy.
Agree a simple rule about what must be checked. A common version is that every number, name, date, quotation and citation in anything external is verified by the person sending it.
Make reporting errors normal. If people feel embarrassed to admit an AI mistake got through, the mistakes will be hidden, and the team will lose the chance to fix the process.
A Simple Verification Policy for an Organization
Organizations benefit from writing the rules down. A one-page policy is usually enough to start.
Define three tiers of output. Internal drafts need a quick read, external content needs fact-checking by the author, and anything legal, financial, medical or safety-related needs review by a qualified person.
Name who is accountable at each tier and how review is recorded. A sign-off in the document history is enough, provided it is consistent.
Review the policy as tools change. Our guide to building an AI risk management framework shows how verification fits into wider controls for small and mid-sized businesses.
Who Should Worry Most, and Who Can Relax
If you are a researcher, a student, a blogger or a publisher, citation and factual hallucinations are your main risk, because your output is judged on accuracy. Check every reference and every figure you did not already know.
If you are a developer or part of a business team, the risk is an error passing into a product, a report or a customer message. Build verification into the process, so it does not depend on someone remembering.
If you work in healthcare, law or finance, treat AI as an assistant to a qualified person and never as the final authority. The stakes in those fields put most tasks at the top of the Risk Ladder.
If you use AI for brainstorming, drafting, rewording or learning the outline of a topic, you can work with far less friction. The consequence of a wrong detail is small, and your own review catches most problems.
What Happens If You Do Not Verify
At first, almost nothing happens. Most answers are fine, the work goes faster, and the problem stays invisible.
Then one incorrect answer gets published, or one fake citation enters a report, or one wrong number reaches a customer. A developer builds on an invented function, and the error surfaces weeks later.
The danger of hallucination lies in where errors travel, more than in how often they occur. A single unverified answer can become content, then a decision, then an automated action with real consequences.
The further AI output travels without a human check, the more expensive one hallucination becomes. A verification habit is cheap insurance against that path.
The Contrarian View: The Best AI Knows When Not to Answer
Most people judge an AI assistant by how often it gives an answer. The research suggests that this standard is part of the problem.
A system that always answers must sometimes guess, because some questions have no reliable answer in its evidence. A perfectly accurate model would still be unsafe if the workflow demanded an answer every time.
The Nature paper reframes hallucination partly as an incentive problem, created when evaluations reward answers more than justified abstention. Change what is rewarded, and behavior changes with it.
That shifts how we should judge AI. The best assistant is sometimes the one that says “I cannot verify that,” and users who value that response will get more reliable tools over time.
Where AI Reliability Is Heading
Reliability is improving on several fronts at once. Models are being trained to abstain more appropriately, to search when they lack information and to use tools for calculation.
Evaluation is changing too. Tests that penalize confident errors more than honest uncertainty give developers a reason to build models that guess less.
No single improvement removes the need for reliability engineering. Organizations that deploy AI still need the governance described in our guide to AI governance, with clear rules about where human review is required.
The likely future is AI that is better at knowing when to answer, when to search, when to ask for clarification and when to decline. That is a more useful goal than an AI that never makes a mistake.
How We Researched This Guide
This guide was researched and drafted with AI assistance and checked against the primary sources linked in the article. The definition of hallucination and the SimpleQA figures come from OpenAI’s published research.
The explanation of statistical pressure and evaluation incentives comes from the 2026 Nature paper, and the healthcare findings come from the systematic review in BMC Health Services Research. The court case is described from the public record of the 2023 sanctions decision.
We did not run our own hallucination benchmark, and no test result is claimed. The Hallucination Risk Ladder, the AI Reliability Stack, the traffic-light rule and the checklists are AI Hustle World frameworks.
Last updated October 2026. This version restructures the guide, adds the verified evaluation figures, the court case, the tools and cost sections, and re-checks every source link.
Final Thoughts
AI hallucinations are not a strange glitch that appears when a chatbot has a bad day. They follow from how language models work and how they are evaluated.
Models learn powerful patterns that let them produce useful answers. Producing a plausible answer is still different from holding reliable evidence, and when systems are rewarded for answering, they will sometimes guess.
You do not need to fear AI to use it well. You need to know when an answer is likely to be reliable, when uncertainty is high and when checking is mandatory.
Give the model evidence, let it say it does not know, check the claims that matter and keep a person in charge of consequential decisions. The best AI system is the one that knows when an answer is not justified, and the best user is the one who checks before it counts.
Want to Make Your AI Workflows More Reliable?
Understanding hallucinations is only the first step. Learn how to verify AI information, improve prompts, and build safer AI-assisted workflows.
Learn How to Verify AI Information →Frequently Asked Questions
What is an AI hallucination?
A plausible but false or unsupported output from an AI system. It can include invented facts, citations, people, numbers, quotations or explanations.
Why does AI hallucinate?
Models generate likely text rather than look up facts, rare details are learned unreliably, and evaluations often reward guessing over admitting uncertainty.
Why does AI sound confident when it is wrong?
Fluency comes from language patterns, not from evidence. A model can produce a polished, detailed answer without reliable support for each claim.
Can AI hallucinations be prevented completely?
No. Risk can be reduced with grounding, retrieval, tools, better prompts, evaluation, verification and human review, but no method removes it entirely.
Does RAG eliminate hallucinations?
No. RAG gives the model relevant evidence and reduces errors, but wrong retrieval, conflicting sources and misreading can still produce unsupported answers.
Do newer AI models hallucinate less?
Often, yes, on standard tests. Hallucinations remain a challenge even for the most advanced models, so verification is still needed.
How can I reduce AI hallucinations?
Provide source material, tell the AI to use only that evidence, ask it to flag uncertainty, check important claims and use stronger controls for high-stakes work.
Should I ask AI to “not hallucinate”?
That instruction alone does little. Specify the evidence it may use and tell it what to do when information is missing.
Are citations from AI always trustworthy?
No. AI can invent citations or misstate what a real source says. Open every important reference and confirm it supports the claim.
What is the safest way to use AI for important decisions?
Treat AI as an assistant, not the final authority. Ground it in authoritative information, verify key claims independently and keep a qualified person in control.
Related Guides
- How to Reduce Hallucinations with RAG: A Practical Guide
- How to Write AI Prompts for More Accurate and Reliable Answers
- How AI Answers Questions: From Prompt to Response Explained
Written by
Muntasir Ahmad Chowdhury
Founder, AI Hustle World
Muntasir Ahmad Chowdhury is the Founder of AI Hustle World, an independent publication dedicated to making Artificial Intelligence practical, trustworthy, and easy to understand. He researches AI tools, automation, customer service, productivity, and real-world business applications, helping readers make smarter technology decisions through research-driven, experience-backed content.
Expertise:
AI Tools • AI Automation • AI Customer Service • AI Productivity • Generative AI • AI Workflows
Get Smarter With AI
Enjoyed this guide? Get practical AI tools, tutorials, and honest reviews delivered to your inbox.